Self-host ggrun
v3.2.12Local LLM launcher with automatic GPU memory placement
- Stars
- 282
- Port
- 8081 (OpenAI-compatible API and Anthropic-compatible endpoint)
What is ggrun?
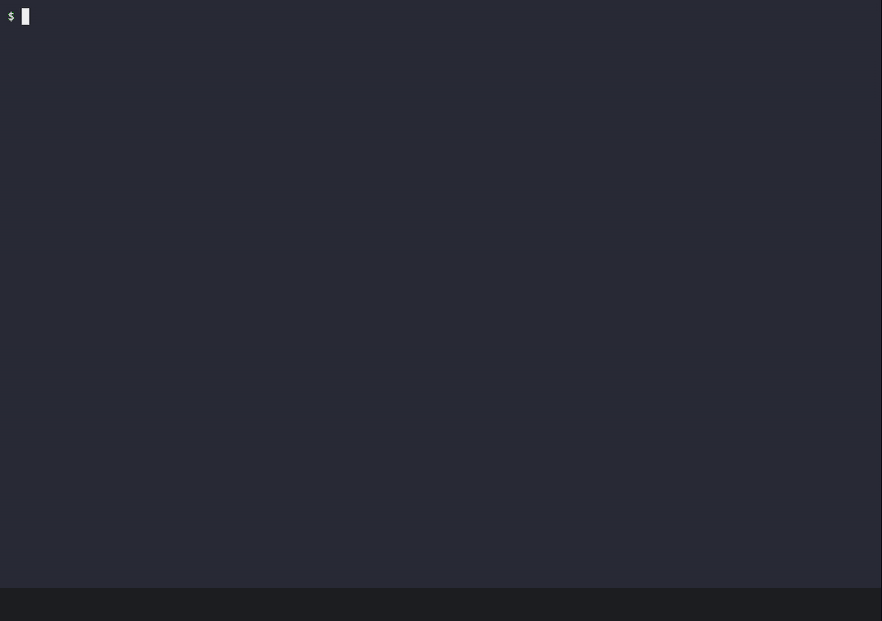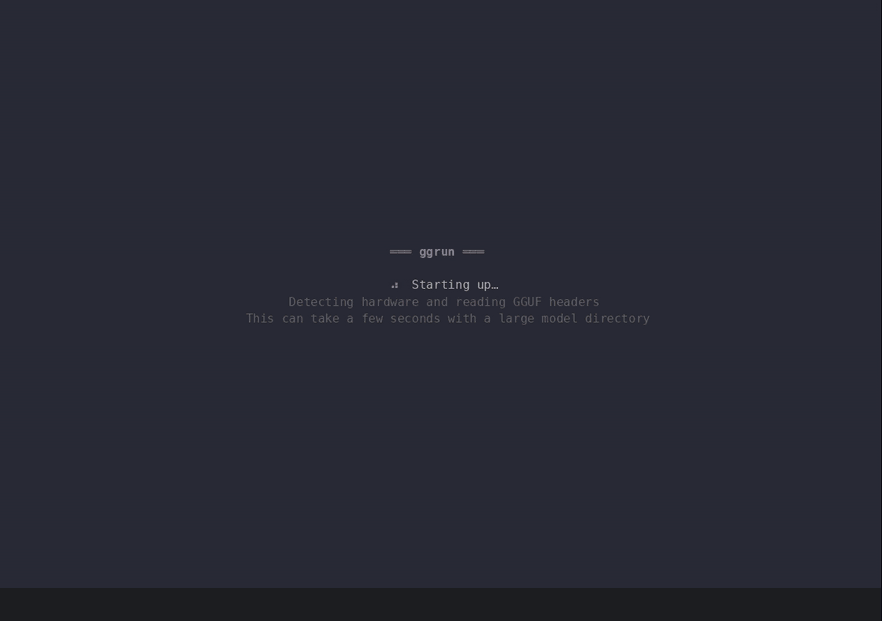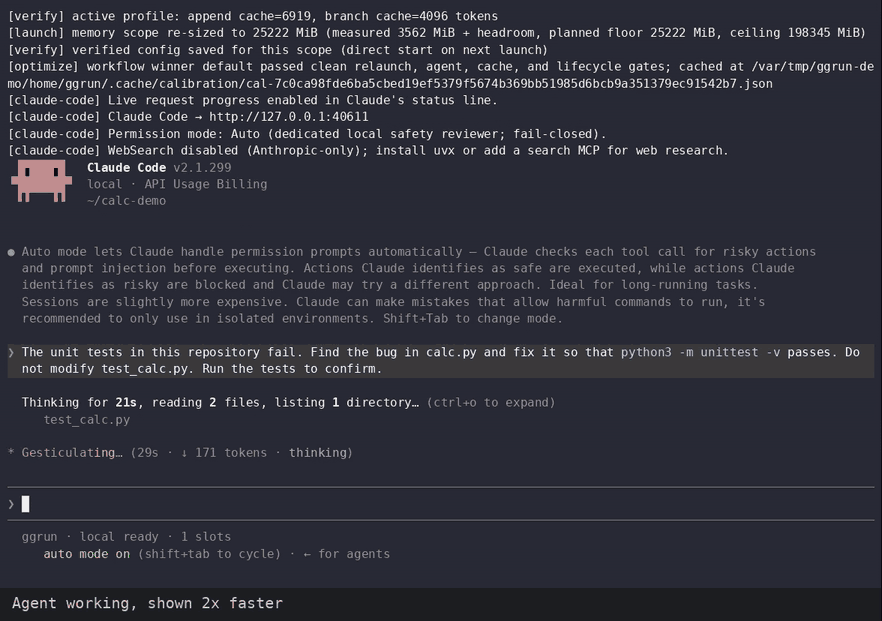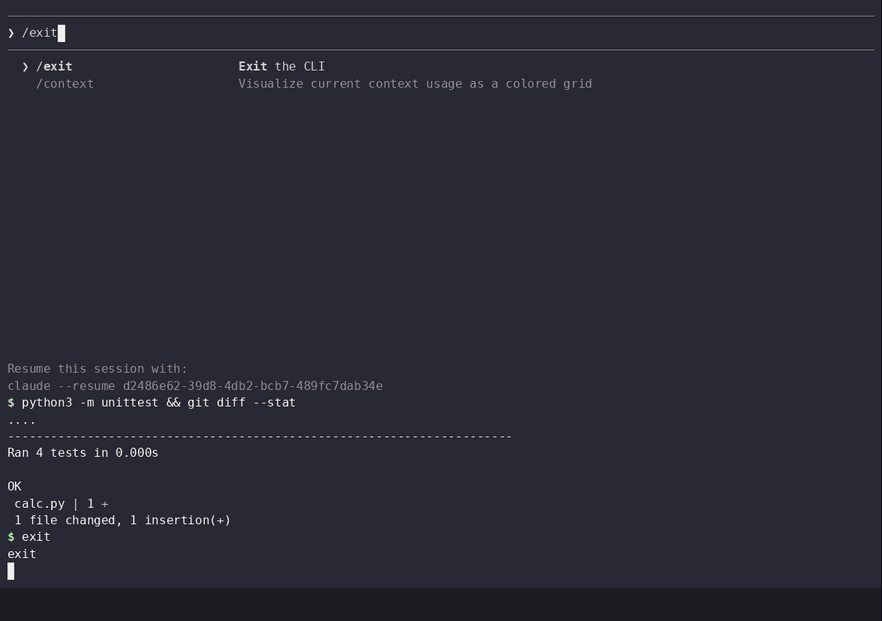
ggrun (from "gguf run") is a launcher for running local large language models on your own hardware. It provides a terminal UI for model discovery, downloads from Hugging Face, backend selection (llama.cpp, ik_llama.cpp, Vulkan), and automatic memory placement across GPUs and system RAM — especially for large MoE models. The tool builds a launch plan from the GGUF metadata and your hardware, checks that the plan fits in available VRAM/RAM, starts the inference server, and provides an OpenAI-compatible /v1 API alongside an Anthropic-compatible endpoint for Claude Code workflows. It supports speculative decoding, AI-assisted tuning of launch flags, and measured performance caching. Installation options include a one-line script, native Windows installer, Docker images (CPU, CUDA, Vulkan), and release bundles for Linux, macOS, and Windows.
Should you self-host ggrun?
ggrun scores 50/100 on selfhost.directory (how scoring works) and ranks #18 of 25 in LLM Inference. It has 282 GitHub stars.
It shipped 11 stable releases in the past year. The latest, v3.2.12, came out on 18 October 2026. New versions land roughly every 2 weeks.
Setup is moderate: expect some configuration beyond a single command. It is MIT-licensed and written mostly in Go.
Its closest alternative on selfhost.directory is AnythingLLM (88/100, 67 666 stars). It scores higher overall, so compare the two before you pick. See ggrun vs AnythingLLM side by side.
Features
- AI-assisted launch tuning
- Anthropic-compatible endpoint for Claude Code
- Benchmark mode
- Dry Run Mode
- Memory probing and validation
- Model discovery and recommendations
- Model download from Hugging Face
- Model Management
- Multi-GPU and CPU memory placement
- NVIDIA bandwidth measurement
- OpenAI Compatible API
- Prompt caching for agent workflows
- Speculative Decoding
- Terminal UI (TUI)
- Vision model support
ggrun README
More in LLM Inference
 gpustackOpen-source, self-hosted GPU cluster manager that deploys LLMs on NVIDIA, AMD or Ascend hardware via vLLM, SGLang and TensorRT-LLM behind OpenAI-compatible APIs.
 jevosOpen-source, self-hosted decision model answering yes/no, choice and score questions with probabilities on a laptop CPU in 28-130 ms, an alternative to Jev's cloud.
 koboldcppSelf-hosted, open-source (AGPL-3.0) single-file GGUF LLM server with a bundled KoboldAI Lite web UI and OpenAI-, KoboldAI- and Ollama-compatible API endpoints.
 lemonadeSelf-hosted, open-source local AI server that runs LLM, vision, image, speech, and transcription models on your own GPU or NPU and serves them through OpenAI-style APIs.
 libre-chatLibre Chat is a self-hosted, open-source chatbot web service powered by local LLMs like Mixtral or Llama 2, with web UI, API, streaming responses, and document-based QA.
 llama.cppllama.cpp is an open-source, self-hosted LLM inference engine written in C/C++ that runs quantized models locally on CPU and GPU with minimal dependencies.
 llamactlSelf-hosted control plane that manages llama.cpp, MLX, and vLLM inference servers through a web dashboard with a unified OpenAI-compatible API.
 llama-gptSelf-hosted, open-source ChatGPT-style chatbot that runs Llama 2 and Code Llama locally, with a web chat UI and an OpenAI-compatible API.
 LLMKubeOpen-source Kubernetes operator running LLMs on NVIDIA, AMD, Intel, and Apple Silicon with pluggable runtimes and hybrid routing.
 LumabriLumabri is a self-hosted, open-source system for running LLMs across LAN computers by distributing layers with donor approval, offering terminal and web chat.
 mistral.rsmistral.rs is a self-hosted, open-source LLM inference engine in Rust serving OpenAI-compatible and Anthropic-compatible APIs with built-in web UI.
 OllamaOllama is a self-hosted, open-source platform for running LLMs locally on macOS, Windows, and Linux with a REST API and official SDKs.
0 comments