Self-host lemonade
v2026.45.3Local AI server for chat, images, and speech on GPU/NPU
sudo dnf install ./lemonade-server-*-fc43.x86_64.rpm- Stars
- 6 157
- Port
- 13305 (HTTP server (API and web GUI))
ghcr.io/lemonade-sdk/lemonade-server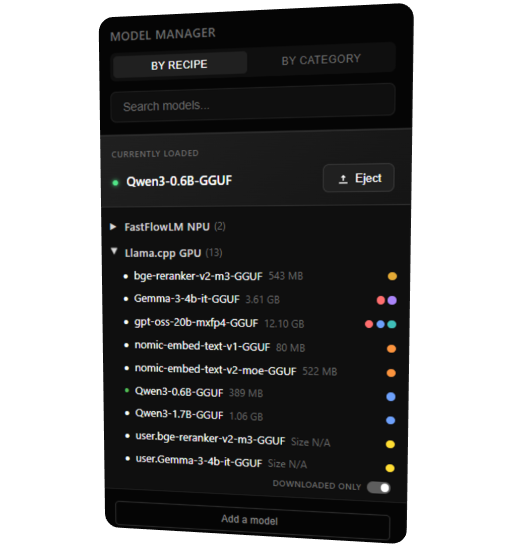
What is lemonade?
Lemonade is an open-source local AI server that aims to provide cloud-API capabilities for free and privately, running chat, coding, speech, and image-generation models on a PC's own NPU and GPU. It ships in two flavors: Lemonade Server, a service exposing OpenAI-, Anthropic-, and Ollama-compatible endpoints plus an MCP gateway, and an embeddable portable binary developers can bundle into their own apps. A CLI and a built-in app (GUI) cover chat, image generation, speech generation, and transcription, and a Model Manager downloads GGUF, FLM, and ONNX models from Hugging Face or ModelScope. Inference is auto-configured across engines such as llama.cpp, whisper.cpp, vLLM, ONNX Runtime, and FastFlowLM, targeting AMD NPUs and GPUs, Apple Silicon, NVIDIA, and plain CPUs. Installers exist for Windows (MSI), Debian, Fedora, Ubuntu, Arch, Snap, and macOS, alongside a GHCR container image; cloud offload can additionally route requests to OpenAI-compatible providers. The project is a community effort with optimizations contributed by AMD engineers, and cloud routing is still marked experimental.
lemonade alternatives
 Turbo-LLMSelf-hosted local LLM platform running any engine with auto-tuning, real measured tokens/sec, and OpenAI/Anthropic APIs for Claude Code.CompareTurbo-LLM with lemonade
 OllamaOllama is a self-hosted, open-source platform for running LLMs locally on macOS, Windows, and Linux with a REST API and official SDKs.CompareOllama with lemonade
 Atomic ChatSelf-hosted desktop/mobile app for running LLMs locally with OpenAI-compatible API. 1000+ models, multiple engines, MCP, agent launching.CompareAtomic Chat with lemonade
 llama.cppllama.cpp is an open-source, self-hosted LLM inference engine written in C/C++ that runs quantized models locally on CPU and GPU with minimal dependencies.Comparellama.cpp with lemonade
 Text Generation WebUIAn open-source, self-hosted LLM chat app you run on your own machine: vision input, tool-calling, LoRA fine-tuning, and an OpenAI/Anthropic-compatible API.CompareText Generation WebUI with lemonade
 obrew-studio-serverSelf-hosted, open-source AI engine that runs LLMs locally with RAG, agents, and workflow automation — no cloud dependency, all data stays on your device.Compareobrew-studio-server with lemonade
 AnythingLLMAnythingLLM is a self-hosted, open-source AI app for document chat, AI agents, and local/cloud LLMs — running on your hardware with no token limits.CompareAnythingLLM with lemonade
 airunnerSelf-hosted, open-source desktop AI engine: local LLM chat companions, Stable Diffusion art generation, TTS/STT voice, and a headless Ollama/OpenAI-compatible API.Compareairunner with lemonade
Should you self-host lemonade?
lemonade scores 71/100 on selfhost.directory (how scoring works) and ranks #8 of 25 in LLM Inference. It has 6 157 GitHub stars, +325 in the last 30 days.
It shipped 41 stable releases in the past year. The latest, pr-3930, came out on 8 November 2026. New versions land roughly every 6 days.
Setup is easy: most people get it running in one sitting. An official Docker image is available. It is Apache-2.0-licensed and written mostly in C++.
Its closest alternative on selfhost.directory is Ollama (95/100, 186 429 stars). It scores higher overall, so compare the two before you pick. See lemonade vs Ollama side by side.
Features
- API Key AuthenticationUnset by default; endpoints are unauthenticated unless keys are set.
- CLI
- Cloud offload routingMarked experimental by the project.
- Embeddable SDK binary
- GPU/NPU/CPU backend auto-selection
- MCP server gateway
- Model aliases with failover
- Model manager and downloader
- Multi-modal local inference
- OpenAI Compatible API
- OpenTelemetry tracing
- Performance stats endpoint
- Web and desktop GUI
lemonade README

FAQ
Can TTS voices be mixed?
Yes, two voices can be mixed using a format like `af_jessica.5+af_kore.4`.
What voices are supported for TTS?
Most of the Kokoro-82M voices list; OpenAI voices come from a default picker and other voices can be typed manually.
How do I use my own llama.cpp or whisper.cpp binaries?
Set environment variables pointing to the full path of your custom llama-server or whisper-server binary instead of the bundled ones.
How do I run Lemonade Server on one PC and access it from another?
Lemonade supports running the server on one machine while using the app from another on the same network; see the Remote Server Connection configuration docs.
Does Lemonade work on older AMD processors or non-Ryzen AI systems?
Yes; it supports Vulkan GPU acceleration on various AMD chips, Radeon GPUs, any x86 CPU, and CPU inference on Intel/NVIDIA systems with GPU support via llama.cpp + Vulkan.
Does LLM inference with the NPU only work on Windows?
On Linux, NPU-only inference is available via FastFlowLM, while Ryzen AI SW's NPU and hybrid inference is currently Windows-only.
Can Lemonade print out stats like tokens per second?
Yes, the /stats endpoint returns performance metrics from the most recent completion request; debug logging and `lemonade logs` are also available.
What's the difference between GGUF and ONNX models?
GGUF works with the llama.cpp backend on CPU and GPU (Vulkan or ROCm), while ONNX runs on OnnxRuntime GenAI and supports NPU and NPU+iGPU hybrid execution.
What models are supported?
A wide range of LLMs including LLaMA, DeepSeek, Qwen, Gemma, Phi and gpt-oss; most GGUF models can also be added by users through the Model Manager or the pull command.
Where are models stored and how do I change that?
Models go to the Hugging Face cache at ~/.cache/huggingface/hub by default, changeable via HF_HOME or HF_HUB_CACHE; a secondary GGUF directory can be scanned with extra_models_dir, and FastFlowLM keeps its models at FLM_MODEL_PATH.
Is Linux supported? What about macOS?
Yes, both are supported. macOS gets a .pkg installer for Apple Silicon using the llama.cpp backend with Metal acceleration.
Which devices are supported?
The Supported Configurations section of the README gives a CPU/GPU/NPU support matrix; NPU details are covered in the hybrid/NPU questions.
How do I install Lemonade SDK or Server?
Follow the installation guide and pick the options that apply to you.
What is Lemonade and what does it include?
An open-source local LLM solution with one-click installers, auto-configured inference engines, an app for setting up and testing LLMs, and LLMs exposed through the OpenAI API standard.
More in LLM Inference
 libre-chatLibre Chat is a self-hosted, open-source chatbot web service powered by local LLMs like Mixtral or Llama 2, with web UI, API, streaming responses, and document-based QA.
- llama.cppllama.cpp is an open-source, self-hosted LLM inference engine written in C/C++ that runs quantized models locally on CPU and GPU with minimal dependencies.
 llamactlSelf-hosted control plane that manages llama.cpp, MLX, and vLLM inference servers through a web dashboard with a unified OpenAI-compatible API.
 llama-gptSelf-hosted, open-source ChatGPT-style chatbot that runs Llama 2 and Code Llama locally, with a web chat UI and an OpenAI-compatible API.
 LLMKubeOpen-source Kubernetes operator running LLMs on NVIDIA, AMD, Intel, and Apple Silicon with pluggable runtimes and hybrid routing.
 LumabriLumabri is a self-hosted, open-source system for running LLMs across LAN computers by distributing layers with donor approval, offering terminal and web chat.
 mistral.rsmistral.rs is a self-hosted, open-source LLM inference engine in Rust serving OpenAI-compatible and Anthropic-compatible APIs with built-in web UI.
- OllamaOllama is a self-hosted, open-source platform for running LLMs locally on macOS, Windows, and Linux with a REST API and official SDKs.
 ollama-intel-gpuA self-hosted Docker image running Ollama on Intel Arc GPUs via IPEX-LLM, drop-in replacement for Nvidia Ollama with same API on port 11434.
 production-stackSelf-hosted, open-source Helm stack that scales vLLM across a Kubernetes cluster, with KV-cache-aware request routing and a Prometheus/Grafana monitoring dashboard.
 ReameSelf-hosted LLM server for CPU inference using ternary models, runs 8B models in 2.2GB RAM on free-tier ARM with OpenAI-compatible API.
 Self-Hosted AI StackOpen-source Docker Compose project running local AI models, chat, documents, voice, and MCP tools on your server with optional HTTPS and GPU acceleration.
0 comments