Self-host llamactl
v0.22.1Unified LLM model router with web dashboard
- Stars
- 160
- Port
- 8080 (Main web dashboard and management API)
What is llamactl?
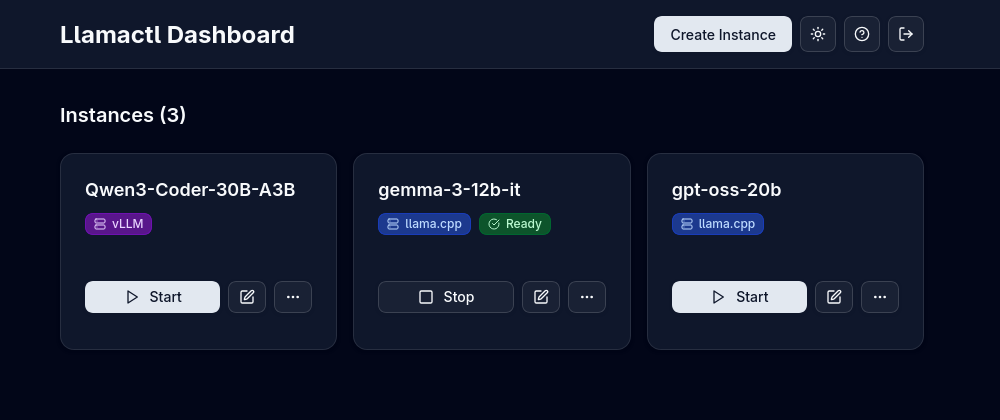
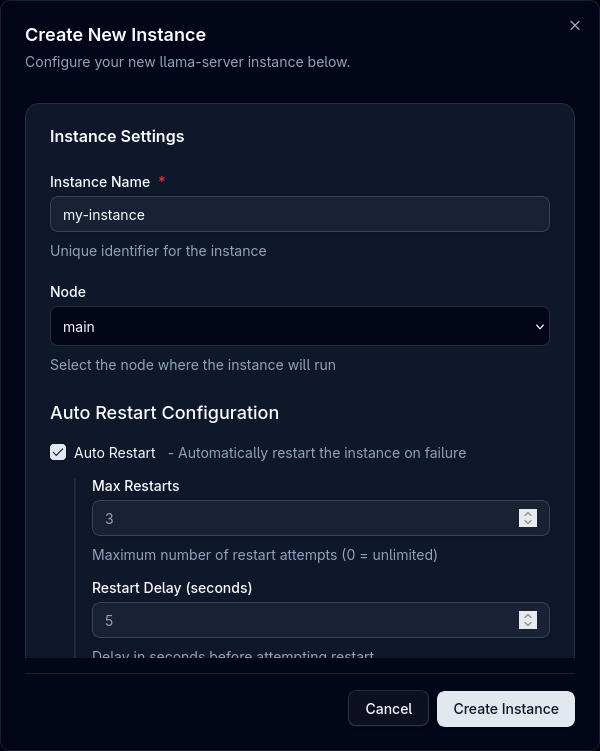
llamactl is a self-hosted control plane that lets you run and manage local LLM inference servers. It handles llama.cpp, MLX on Apple Silicon, and vLLM through one web dashboard, exposing a single OpenAI-compatible API that directs requests to specific model instances. You get a built-in HuggingFace downloader for GGUF and Safetensors models, a llama.cpp router that loads models only when needed, automatic idle shutdown and least-recently-used cleanup, grouped instance limits, and the ability to run instances on remote machines. The dashboard and management API use API keys, while inference endpoints use separate keys; you can also add OpenID Connect login via Authentik, Keycloak, or Authelia. Built with Go and React, it defaults to port 8080 and uses a local SQLite database with no extra services required. Install via pre-built binaries, Docker images with GPU support, or compile from source using Go 1.24+ and Node.js 22+.
Should you self-host llamactl?
llamactl scores 44/100 on selfhost.directory (how scoring works) and ranks #22 of 25 in LLM Inference. It has 160 GitHub stars.
It shipped 16 stable releases in the past year. The latest, v0.22.1, came out on 25 October 2026. New versions land roughly every 2 weeks.
Setup is moderate: expect some configuration beyond a single command. It is MIT-licensed and written mostly in Go.
Its closest alternative on selfhost.directory is Ollama (95/100, 185 098 stars). It scores higher overall, so compare the two before you pick. See llamactl vs Ollama side by side.
Features
- Anthropic messages endpoint
- Built-in model downloader
- Custom backends
- Distributed deployment
- Instance groups with limits
- Log Rotation
- Multi-backend LLM management
- OIDC/SSO Authentication
- OpenAI Compatible API
- REST API
- Smart resource management
- Web Dashboard
llamactl README
More in LLM Inference
 llama-gptSelf-hosted, open-source ChatGPT-style chatbot that runs Llama 2 and Code Llama locally, with a web chat UI and an OpenAI-compatible API.
 LLMKubeOpen-source Kubernetes operator running LLMs on NVIDIA, AMD, Intel, and Apple Silicon with pluggable runtimes and hybrid routing.
 LumabriLumabri is a self-hosted, open-source system for running LLMs across LAN computers by distributing layers with donor approval, offering terminal and web chat.
 mistral.rsmistral.rs is a self-hosted, open-source LLM inference engine in Rust serving OpenAI-compatible and Anthropic-compatible APIs with built-in web UI.
 OllamaOllama is a self-hosted, open-source platform for running LLMs locally on macOS, Windows, and Linux with a REST API and official SDKs.
 ollama-intel-gpuA self-hosted Docker image running Ollama on Intel Arc GPUs via IPEX-LLM, drop-in replacement for Nvidia Ollama with same API on port 11434.
 production-stackSelf-hosted, open-source Helm stack that scales vLLM across a Kubernetes cluster, with KV-cache-aware request routing and a Prometheus/Grafana monitoring dashboard.
 ReameSelf-hosted LLM server for CPU inference using ternary models, runs 8B models in 2.2GB RAM on free-tier ARM with OpenAI-compatible API.
 Self-Hosted AI StackOpen-source Docker Compose project running local AI models, chat, documents, voice, and MCP tools on your server with optional HTTPS and GPU acceleration.
 sglangSGLang is an open-source, self-hosted inference framework for LLMs and multimodal models with OpenAI-compatible API.
 ShimmyA self-hosted, open-source LLM inference server: a single Rust binary that serves GGUF models through an OpenAI-compatible API, as an alternative to Ollama.
 SmarterRouterSelf-hosted AI gateway that automatically routes queries to the best local or cloud LLM based on prompt analysis, with VRAM management and OpenAI-compatible API.
0 comments