Self-host crawler-buddy
6.2.11HTTP crawling server with unified JSON API for web scraping
- Stars
- 258
- Port
- 3000 (HTTP crawling server API)
rozbujnik/crawler-buddy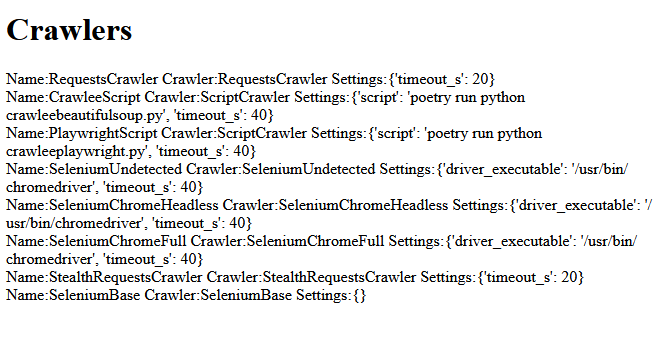
What is crawler-buddy?
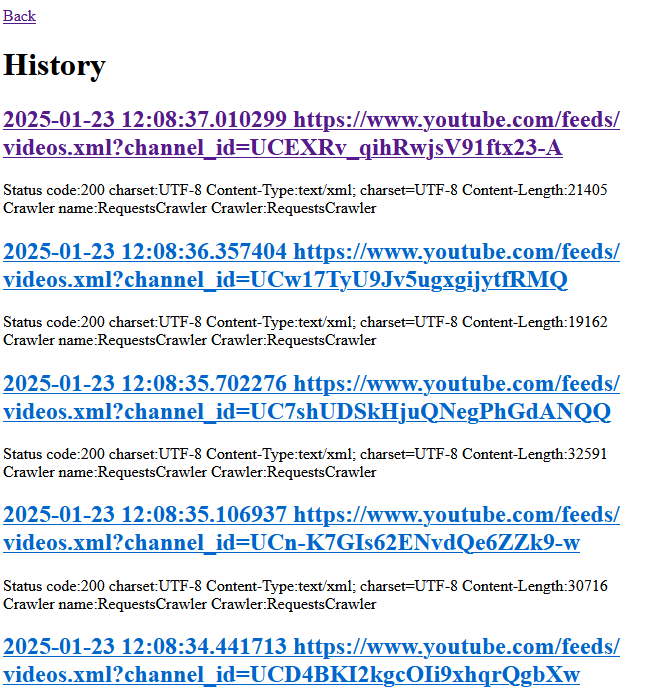
Crawler Buddy is a self-hosted HTTP crawling server that delivers web content and metadata in a consistent JSON format. It provides a unified interface for extracting titles, descriptions, thumbnails, publication dates, RSS feed URLs, social media data, and link metadata from web pages. The server supports multiple crawling methods including Requests, Selenium (headless and full), curl-cffi, httpx, stealth-requests, Crawlee (BeautifulSoup and Playwright), and Scrapy, with automatic method selection based on URL patterns. It can discover RSS feeds for websites and YouTube channels, extract social media metrics from platforms like YouTube, HackerNews, GitHub, and Reddit, and parse RSS/Atom, OPML, and HTML files. The server runs as a Flask application on port 3000 and is deployed via Docker Compose, which includes Chrome and Chromedriver for browser-based crawling. All responses are UTF-8 encoded. The project is licensed under GPL-3.0 and written in Python.
Should you self-host crawler-buddy?
crawler-buddy scores 43/100 on selfhost.directory (how scoring works) and ranks #14 of 16 in Web Scraping. It has 258 GitHub stars.
There was no stable release in the past 12 months, so check the repository's recent activity before you rely on it.
Setup is moderate: expect some configuration beyond a single command. An official Docker image is available. It is GPL-3.0-licensed and written mostly in HTML.
Its closest alternative on selfhost.directory is firecrawl (91/100, 196 199 stars). It scores higher overall, so compare the two before you pick. See crawler-buddy vs firecrawl side by side.
Features
- Automatic RSS feed discovery
- Crawl history and queue management
- Link and domain scanning
- Multiple crawling backends
- RSS/Atom/OPML/HTML file parsing
- Social media metadata extraction
- Unified JSON API for web crawling
- URL-based crawler selection
- Web archive integration
crawler-buddy README
FAQ
How to use the output programmatically?
Use the RemoteServer and Url classes from the webtoolkit library.
Does it support proxy?
Initial proxy support exists for Selenium but is unverified as the author does not use proxies.
What if someone wants to make two parallel crawling methods, to make crawling faster?
Call the /getj endpoint twice with different crawling methods and use the first received response.
More in Web Scraping
 crwfastCRW is a self-hosted, open-source web scraping and search API in Rust with Firecrawl-compatible endpoints and native MCP server for AI agents.
 figraniumFigranium is a self-hosted, open-source browser automation platform for building visual workflows and triggering them via REST API with scheduling and proxy rotation.
 firecrawlSupercharge your AI agents with data from the web and beyond. Building the library for superintelligence. 🔥
 flaresolverrSelf-hosted open-source proxy that drives a real Chrome browser to solve Cloudflare and DDoS-Guard challenges, returning cookies and HTML to your HTTP clients.
 flight-finderSelf-hosted, open-source travel price tracker for flights, hotels, and car rentals using your own AI provider, with interactive charts and VPN price comparison.
 FredyFredy monitors 29 European property portals, deduplicates listings, calculates affordability and travel times, sends notifications via Slack, Telegram, Email, Discord.
 gpt-researcherSelf-hosted, open-source deep research agent: a planner splits your question, parallel researchers scan 20+ web or local sources, and it writes a cited report.
 HuginnSelf-hosted, open-source automation server where agents watch websites, RSS, mail and webhooks, then act on events and post to Slack, Telegram and other services.
 job-opsJobOps is a self-hosted, open-source job-search pipeline that pulls listings from 10+ job boards, scores fit with AI, rewrites your CV per role, and tracks every reply.
 KibitzrKibitzr is a self-hosted, open-source web monitoring tool that checks pages for changes and sends notifications via email, Slack, Telegram, and more.
 LightpandaOpen-source, self-hosted headless browser written in Zig for scraping, crawling and AI agents; serves CDP and WebDriver BiDi on port 9222 for Puppeteer and Playwright.
 Marginalia SearchAn open-source internet search engine with its own crawler and index that you can self-host to rank text-heavy, non-commercial sites on a single server.
0 comments