Self-host crw
v0.39.0Open-source web scraper and search API for AI agents
- Stars
- 1 189
- Port
- 3000 (REST API server)
ghcr.io/fastcrw/crw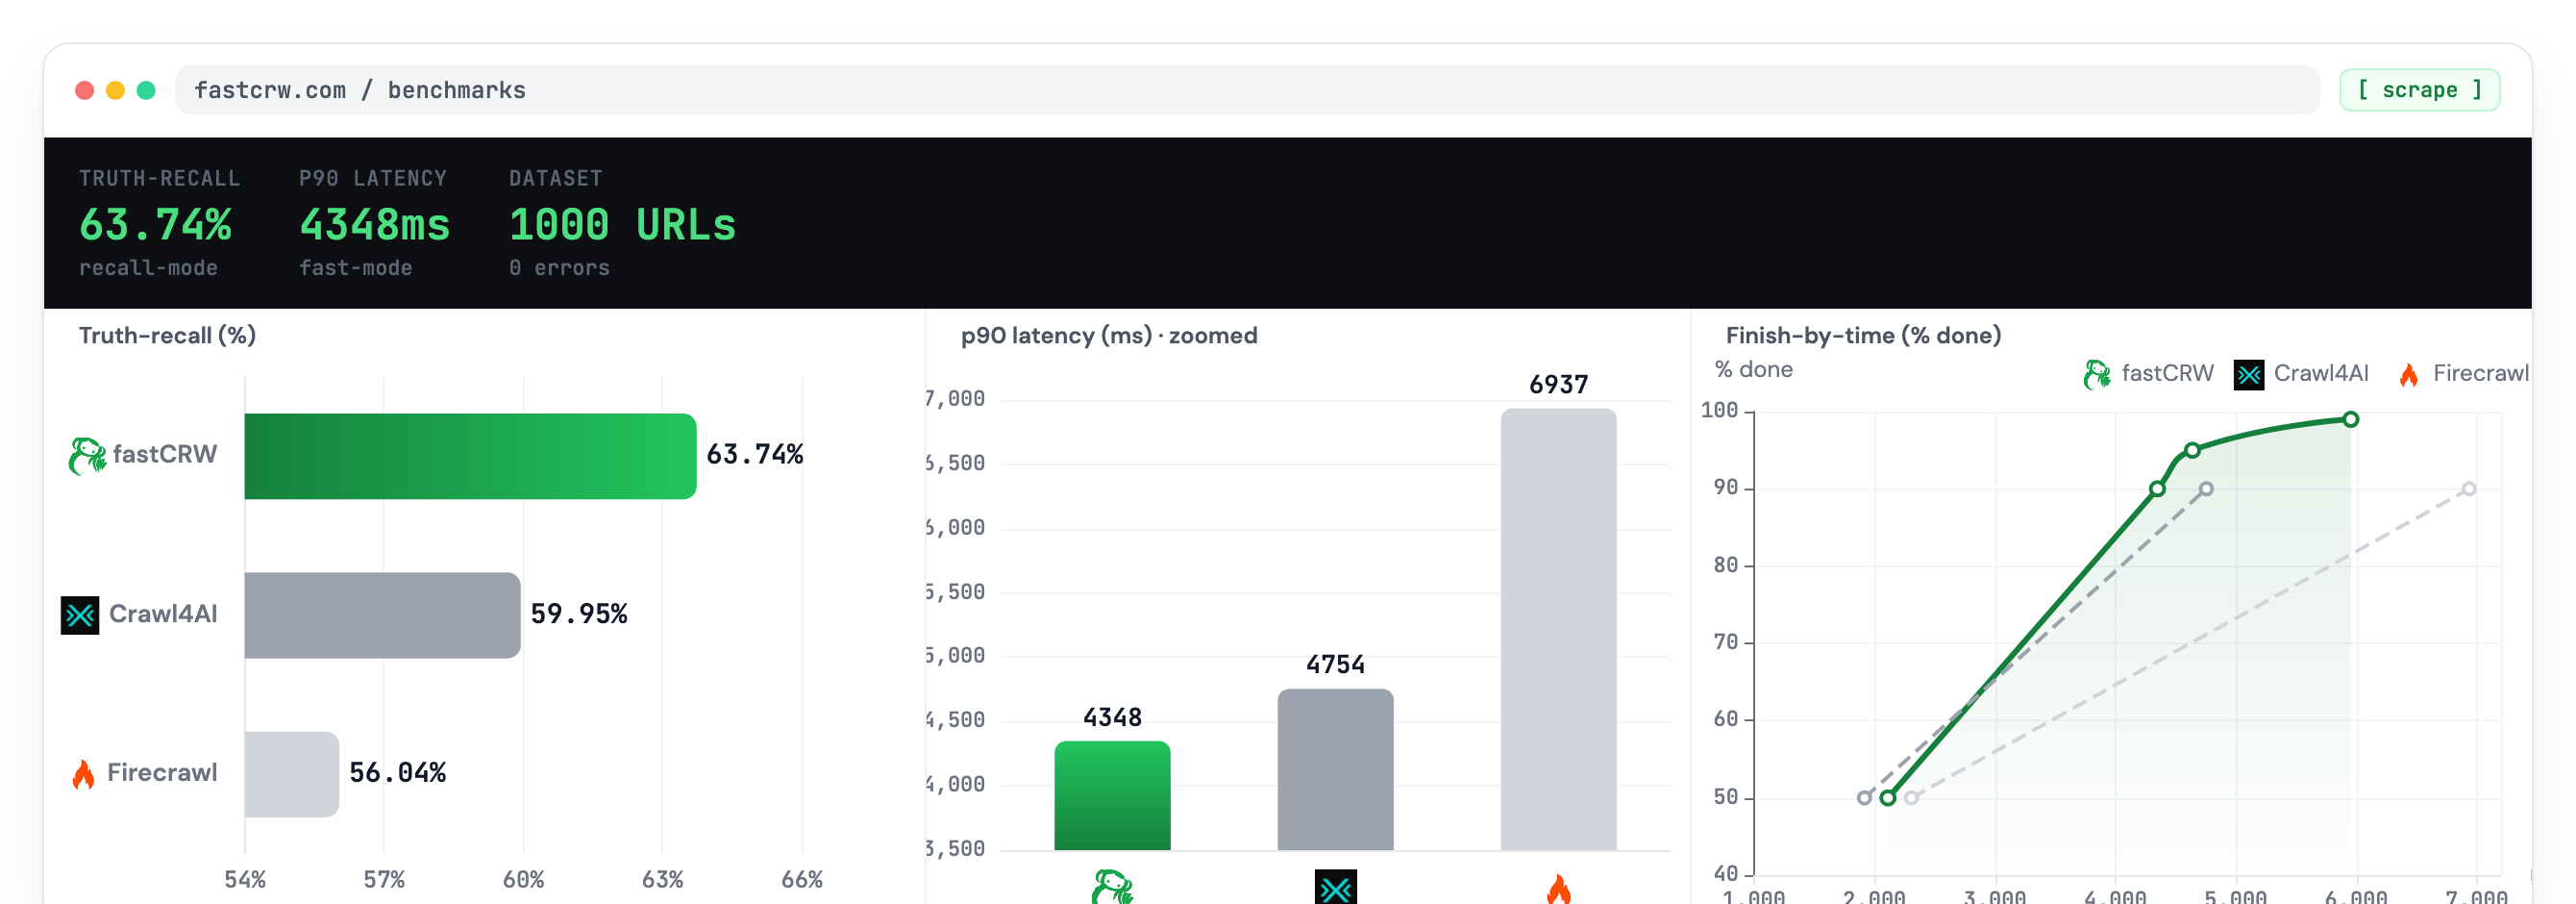
What is crw?
fastCRW is a web scraping and search API designed for AI agents, offering a Firecrawl-compatible REST API with endpoints for scraping single URLs, crawling entire sites, mapping domain URLs, searching the web, and extracting structured data via JSON schemas. It runs as a single ~8 MB Rust binary with optional JavaScript rendering via LightPanda or Chrome CDP. The self-hosted version is free under AGPL-3.0 and can be deployed via Docker, Homebrew, APT, or direct binary download. It includes a native Model Context Protocol (MCP) server for integration with AI coding tools like Claude Code, Cursor, and Windsurf. The hosted cloud version offers managed infrastructure with a free tier of 1000 credits and paid plans from $13/month.
Should you self-host crw?
crw scores 58/100 on selfhost.directory (how scoring works) and ranks #10 of 16 in Web Scraping. It has 1 189 GitHub stars.
It shipped 22 stable releases in the past year. The latest, v0.39.0, came out on 21 October 2026. New versions land roughly every 1 days.
Setup is moderate: expect some configuration beyond a single command. An official Docker image is available. It is AGPL-3.0-licensed and written mostly in Rust.
Its closest alternative on selfhost.directory is webclaw (63/100, 2 403 stars). It scores higher overall, so compare the two before you pick. See crw vs webclaw side by side.
Features
- Anti-DetectionStealth profile uses browserless/chromium (SSPL-3.0)
- Change Monitoring
- Firecrawl-compatible APIResponse field names and error envelopes have minor divergence
- Interactive scraping actions
- JavaScript RenderingOptional; requires separate renderer sidecar
- MCP Server
- PDF parsing
- Selective caching
- Site mapping
- Source attribution
- Structured extractionRequires LLM key (server-side or BYOK)
- Web Crawling
- Web Scraping
- Web SearchRequires search backend in self-hosted deployment
crw README
FAQ
Can I migrate from Firecrawl?
fastCRW is Firecrawl-compatible on the overlap surface (/scrape, /crawl, /map, /search). Endpoint structure and request shape match closely; response field names and error envelopes have minor divergence, so most migrations are small adjustments.
How is fastCRW cheaper?
Standard plan is $69/mo for 100,000 credits with one credit pool covering all endpoints. Self-hosting the AGPL-3.0 engine is free: $0 per 1,000 scrapes versus $0.83–5.33 on Firecrawl's hosted tiers.
Why choose fastCRW over Firecrawl?
fastCRW has the highest truth-recall (63.74% vs Firecrawl's 56.04%) on Firecrawl's own scrape dataset, is written in Rust for performance, is AGPL-3.0 with reproducible benchmarks, and has identical API between self-hosted and cloud.
Does fastCRW support structured JSON extraction with a schema?
Yes. Send formats: ["json"] together with a jsonSchema in your scrape request and fastCRW returns validated structured data using LLM function calling. Extraction runs on fastCRW's managed LLM on paid plans.
Is there an MCP server?
Yes. Native Model Context Protocol support. Connect fastCRW to Claude, Cursor, Windsurf, or any MCP-compatible AI agent. One command to start.
Do responses include source attribution?
Yes. Every response includes source URLs and metadata, so users can verify where an answer came from and teams can debug the pipeline.
Does fastCRW handle JavaScript-rendered pages?
Yes. Built-in browser rendering handles SPAs, React apps, and dynamic content. No Puppeteer or Playwright to install: the browser engine is orchestrated by the fastCRW binary itself.
Can I self-host fastCRW?
Yes. fastCRW is fully open source (AGPL-3.0). Docker setup takes under 5 minutes. Self-hosting is free: you only pay for the cloud API if you want managed infrastructure.
More in Web Scraping
 figraniumFigranium is a self-hosted, open-source browser automation platform for building visual workflows and triggering them via REST API with scheduling and proxy rotation.
 firecrawlSupercharge your AI agents with data from the web and beyond. Building the library for superintelligence. 🔥
 flaresolverrSelf-hosted open-source proxy that drives a real Chrome browser to solve Cloudflare and DDoS-Guard challenges, returning cookies and HTML to your HTTP clients.
 flight-finderSelf-hosted, open-source travel price tracker for flights, hotels, and car rentals using your own AI provider, with interactive charts and VPN price comparison.
 FredyFredy monitors 29 European property portals, deduplicates listings, calculates affordability and travel times, sends notifications via Slack, Telegram, Email, Discord.
 gpt-researcherSelf-hosted, open-source deep research agent: a planner splits your question, parallel researchers scan 20+ web or local sources, and it writes a cited report.
 HuginnSelf-hosted, open-source automation server where agents watch websites, RSS, mail and webhooks, then act on events and post to Slack, Telegram and other services.
 job-opsJobOps is a self-hosted, open-source job-search pipeline that pulls listings from 10+ job boards, scores fit with AI, rewrites your CV per role, and tracks every reply.
 KibitzrKibitzr is a self-hosted, open-source web monitoring tool that checks pages for changes and sends notifications via email, Slack, Telegram, and more.
 LightpandaOpen-source, self-hosted headless browser written in Zig for scraping, crawling and AI agents; serves CDP and WebDriver BiDi on port 9222 for Puppeteer and Playwright.
 Marginalia SearchAn open-source internet search engine with its own crawler and index that you can self-host to rank text-heavy, non-commercial sites on a single server.
 maxunSelf-hosted and open-source web data platform: build scrape, crawl, extract, search and monitor robots in a no-code recorder or with an API, SDK, CLI or MCP.
0 comments