Self-host questdb
10.2.0Apache-2.0 time-series SQL database for event streams
$ docker run -p 9000:9000 -p 8812:8812 -p 9003:9003 questdb/questdb:10.0.1- Stars
- 17 530
- Ports
- 9000 (REST API and Web Console), 8812 (PostgreSQL Wire Protocol), 9003 (Health endpoint), 9009 (InfluxDB Line Protocol over legacy TCP (HTTP ingest is preferred))
questdb/questdb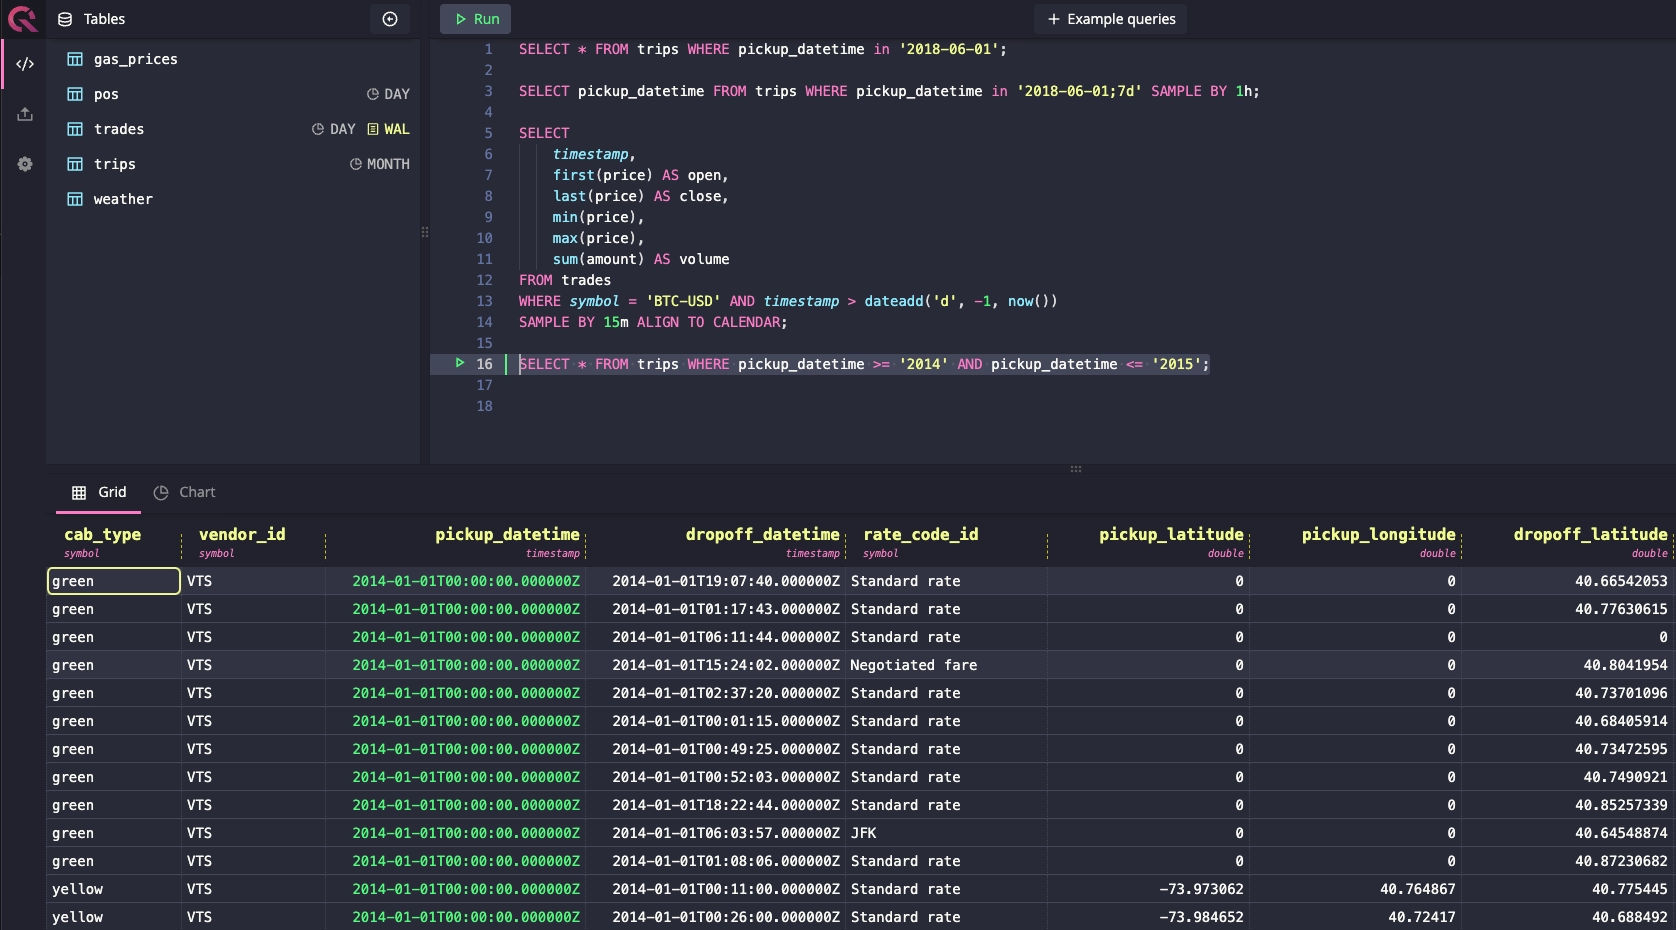
What is questdb?
QuestDB is an Apache-2.0 licensed database purpose-built for time-series data such as telemetry, sensor feeds and market data. To keep latencies tight it leans on a garbage-collection-free Java core plus native C++ and Rust routines, storing values in memory-mapped column files split by time.
Queries use standard SQL with time-oriented extras: SAMPLE BY for downsampling, LATEST ON, and ASOF, WINDOW or HORIZON joins, alongside materialized views and live views, the latter shipped in beta with version 10. Ordering problems are handled by the engine itself, which deduplicates rows and corrects late arrivals. Data lands through the binary QuestDB Wire Protocol, an HTTP REST endpoint, InfluxDB Line Protocol, or a Postgres-compatible listener, and it goes to a write-ahead log before reaching the native partitions; partitions can also be converted to Parquet so outside tooling can read them.
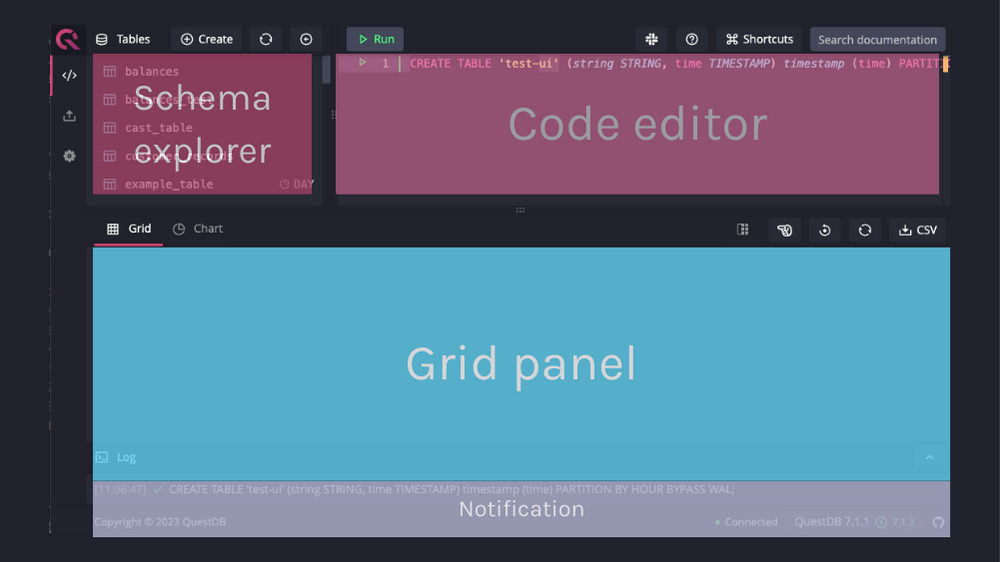
Each instance ships a browser console: SQL editor, notebooks with live charts, schema explorer, CSV upload, query log, metrics panels, and an opt-in AI assistant that uses your own model keys.
Self-hosting means one container image, the Homebrew formula, tarballs for Linux and Windows, a Java-free build for other platforms, plus Helm charts and a systemd guide. A separate port serves health checks. Replication, RBAC, TLS, single sign-on, audit trails and automatic cold-tiering to object storage are Enterprise features, not part of the free core.
questdb alternatives
 databendSelf-hosted, open-source data warehouse in Rust for large-scale analytics plus vector and full-text search, with Python UDF sandboxes and git-like data branching.Comparedatabend with questdb
 tdengineSelf-hosted open-source time-series database for IoT and industrial data, offering clustering, stream processing, subscriptions, TDgpt AI and Grafana or Kafka links.Comparetdengine with questdb
 Apache IoTDBApache IoTDB is a self-hosted, open-source time-series database for industrial IoT with high-throughput reads/writes, ultra-high compression, and SQL-like queries.CompareApache IoTDB with questdb
 ArcadeDBOpen-source, self-hosted multi-model database: one ACID engine for graph, document, key-value, vector, full-text and time-series data, queried in SQL, Cypher or Gremlin.CompareArcadeDB with questdb
 gigapipeSelf-hosted open-source observability backend merging four telemetry types into ClickHouse with Loki, Prometheus, Tempo and Pyroscope protocol support.Comparegigapipe with questdb
 automqSelf-hosted, open-source Apache Kafka fork with stateless brokers that store logs on S3 or MinIO and rebalance partitions in seconds.Compareautomq with questdb
 timeplusSelf-hosted, open-source streaming SQL engine for real-time analytics and AI — a lightweight alternative to ksqlDB and Flink powered by ClickHouse.Comparetimeplus with questdb
 LibreDB StudioSelf-hosted, open-source SQL IDE covering 41 database engines in one browser tab, with OIDC SSO, RBAC, query auditing and an AI query agent — MIT licensed.CompareLibreDB Studio with questdb
All self-hosted alternatives to Kdb+ → All self-hosted alternatives to ClickHouse → All self-hosted alternatives to InfluxDB →
Should you self-host questdb?
questdb scores 76/100 on selfhost.directory (how scoring works) and ranks #4 of 5 in Time Series. It has 17 530 GitHub stars, +90 in the last 30 days.
It shipped 14 stable releases in the past year. The latest, 10.2.0, came out on 10 November 2026. New versions land roughly every 3 weeks.
Setup is easy: most people get it running in one sitting. An official Docker image is available. It is Apache-2.0-licensed and written mostly in Java.
Its closest alternative on selfhost.directory is victoriametrics (78/100, 18 112 stars). It scores higher overall, so compare the two before you pick. See questdb vs victoriametrics side by side.
Features
- Apache Arrow result streaming
- Apache Parquet storage
- High-throughput ingestion
- InfluxDB Line Protocol support
- Live viewsIntroduced in beta with QuestDB 10.0.
- Materialized Views
- Metrics & Monitoring
- Notebooks and dashboards
- Out-of-order and duplicate handling
- PostgreSQL wire compatibility
- QuestDB Wire Protocol
- REST API
- Time-series SQL extensions
- Web Console
- Write-ahead log and columnar partitions
questdb README
English | 简体中文
How to install questdb
Install questdb with Docker
docker run -p 9000:9000 -p 8812:8812 -p 9003:9003 questdb/questdb:10.0.1
Exposes the Web Console (9000), PostgreSQL wire (8812) and health endpoint (9003).
Install questdb with Linux
JAVA_HOMEtar -xvf questdb-10.0.1-rt-linux-x86-64.tar.gz
./questdb.sh start
Packages for Linux and Windows embed the runtime; the default root is $HOME/.questdb on Linux and C:\Windows\System32\qdbroot on Windows. A no-JVM package exists for platforms such as ARM Linux.
Install questdb with Homebrew
brew install questdb
questdb start
questdb stop
macOS on Apple Silicon; root directory is /opt/homebrew/var/questdb. QuestDB bundles native libraries for Apple Silicon only, on an Intel Mac use the Docker image.
How to configure questdb
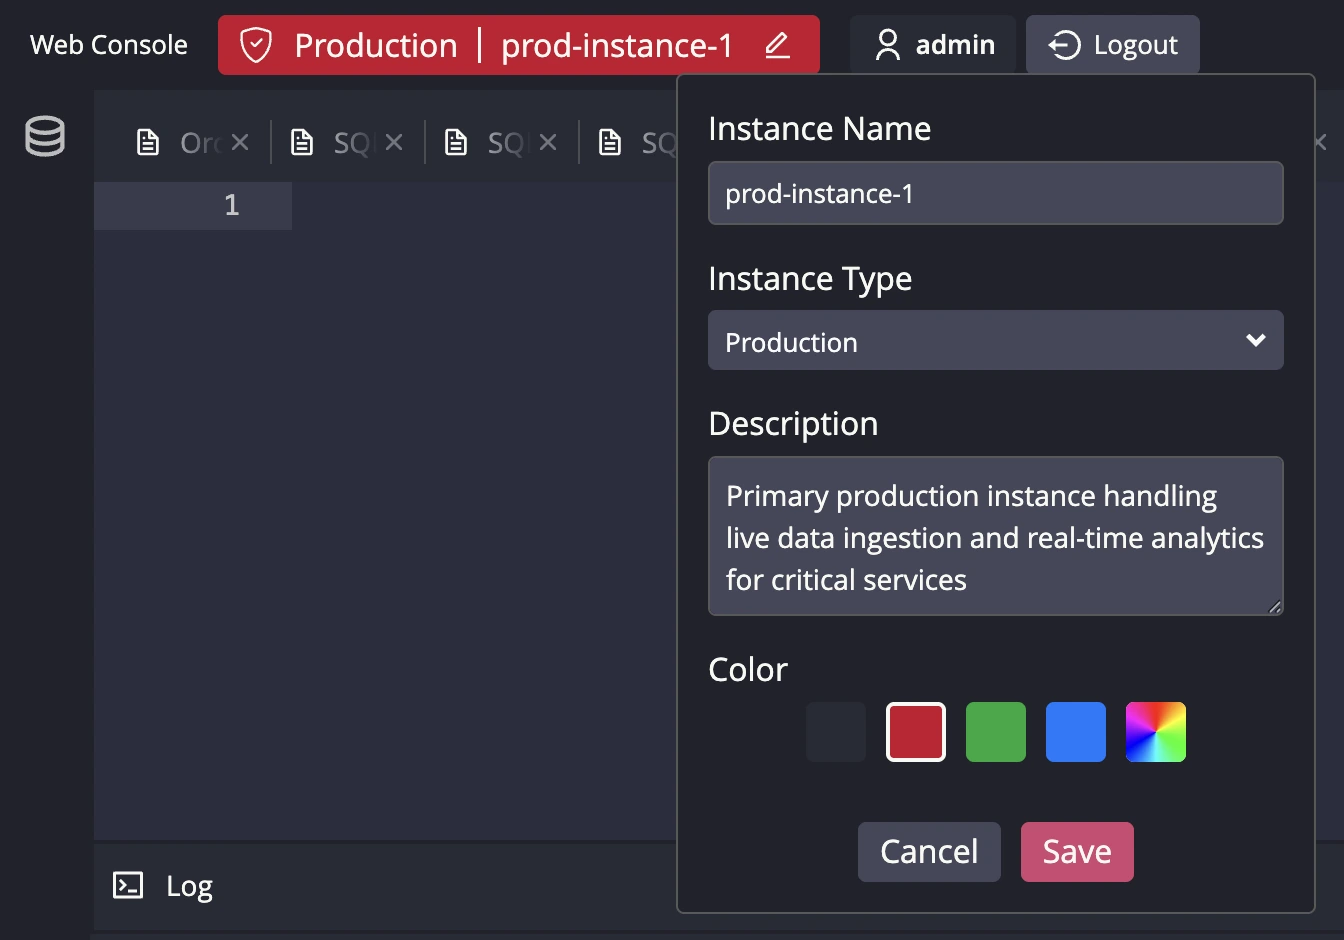
pg.userserver.conf property naming the user allowed to connect over the PostgreSQL wire protocolpg.passwordserver.conf property holding the password used for PostgreSQL wire protocol authenticationpg.readonly.userserver.conf property for the read-only PostgreSQL wire protocol userpg.readonly.passwordserver.conf property for the read-only PostgreSQL wire protocol passwordhttp.settings.readonlyWhen true, the Web Console instance information is not editablevalues: true | false
questdb releases & version history
AI summary New features and fixes for materialized views and QWP ingestion
QuestDB 10.2.0
QuestDB 10.2.0 adds GROUPING SETS, ROLLUP and CUBE, row-level retention for materialized views, a DEDUP SKIP mode that keeps the first-written row, and opt-in power-loss durability for WAL tables, enabled with cairo.commit.mode=adaptive. QWP ingestion of small messages is much faster, and this release fixes a large batch of wrong-result, crash and hang bugs in queries, out-of-order ingestion and Parquet partitions.
This release contains a few breaking changes. Read the Breaking changes section before you upgrade, especially if you create materialized views with LIMIT or window functions, send the designated timestamp twice over QWP, or may need to downgrade after using DEDUP SKIP.
For any questions or feedback, please join us on Slack or on Discourse.
See also our prettier release notes page.
Breaking changes 💥
CREATE MATERIALIZED VIEWrejectsLIMITin queries that read the base table, and base-table window functions nested in expressions orSAMPLE BYsubqueries. Replaying olderSHOW CREATEoutput that contains them fails. #7263- QWP rejects table blocks that carry the designated timestamp twice, once through
at(...)and once as a named column. Before this change, QuestDB accepted them and stored wrong timestamps. A sender that uses both forms on one table now gets a schema error on every later batch for that table. #8052 - An unknown
cairo.commit.modevalue now fails startup, instead of silently selectingnosync. #7411 - After 10.2.0 has run on a database, downgrading, writing with the older version and upgrading again is not supported. See downgrade to an earlier release. #7411
- Downgrading after using
DEDUP SKIP: older versions treatSKIPtables asUPSERTwithout an error, and suspend WAL apply when they replay a loggedALTER TABLE ... DEDUP SKIP. #7885
Highlights
GROUPING SETS, ROLLUP and CUBE
GROUP BY and SAMPLE BY now accept ROLLUP, CUBE and GROUPING SETS, with the GROUPING() and GROUPING_ID() functions. One query returns subtotals and a grand total in a single scan of the input:
SELECT symbol, side, sum(amount)
FROM trades
GROUP BY ROLLUP(symbol, side);
Grouping sets run in parallel where the plan allows. SAMPLE BY grouping sets support FILL with NULL, constants or NONE. cairo.sql.max.grouping.sets caps how many grouping sets one query expands to (default 4096). Grouping sets do not vectorize: they ran 1.4x slower than the equivalent UNION ALL of plain GROUP BYs serially, and up to 6.9x slower in parallel, in the PR's benchmark. #6853
Passthrough views and row-level retention
Materialized views can now be passthrough views: a filtered copy of a table (SELECT ... WHERE, no SAMPLE BY), kept up to date as rows arrive. The new EXPIRE ROWS policy adds row-level retention on top, and hides expired rows of a materialized view from every query: WHEN <predicate>, KEEP LATEST, KEEP [N] HIGHEST|LOWEST, or a window predicate. For monotonic WHEN policies, such as ts < now(), a background job also frees the disk; cairo.mat.view.row.expiry.cleanup.* settings control it. ALTER MATERIALIZED VIEW ... SET EXPIRE ROWS and ... DROP EXPIRE change a view's policy. #7263
DEDUP SKIP: keep the first row
The new DEDUP SKIP mode keeps the first-written row and drops later duplicates, where UPSERT keeps the last one. CREATE TABLE, CTAS and ALTER TABLE ... DEDUP accept it, and SHOW CREATE TABLE prints it. Commits that hold only duplicates leave native and Parquet partitions untouched, and resending unchanged rows into DEDUP UPSERT Parquet partitions no longer rewrites them. #7885
Power-loss durability for WAL tables (opt-in)
cairo.commit.mode=adaptive makes WAL tables survive power loss for much less than sync mode costs. QuestDB flushes the WAL on commit, applies it to table files without per-apply flushes, and rebuilds the table files from the WAL after a crash, so the server restarts with consistent tables instead of failing on a damaged partition. cairo.adaptive.commit.group.window (default 50 ms) batches flushes across commits, so commits acknowledged within the last window can be lost. Pair it with request_durable_ack=local on QWP clients (local,replicated on QuestDB Enterprise) to be told when each batch is on disk, or set the window to 0. The default stays nosync. #7411
Faster ingestion
- QWP over WebSocket ingests one-row messages at about 3.9M rows/s, up from about 210k, on the PR's benchmark. Large messages are unchanged. The wire protocol and ack semantics are unchanged. #8110
- WAL apply no longer falls back to slow one-by-one mode on backlogs of small out-of-order transactions that span a wide timestamp range, where it could fall behind ingestion indefinitely. #8008
- With
cairo.file.async.munmap.enabled, a released file mapping stays cached until the background job unmaps it, so reopening the same file reuses it without a newmmap. #7751
Storage and operations
- Repair Parquet indexes after upgrading from 9.3.4-10.0.1. Those versions could leave stale metadata after merging out-of-order rows into Parquet partitions, so index scans could miss rows and deduplication could keep duplicates.
ALTER TABLE ... FORCE REINDEX PARQUETrepairs affected partitions online;ADD INDEXand out-of-order writes repair them automatically. Until a partition is repaired, index queries on it fail withindex does not cover parquet partition datainstead of returning wrong rows. #8139 - Quiet QWP connections no longer block WAL cleanup. A connection idle for
qwp.min.idle.ms.before.writer.release(default 30s,0disables) releases its WAL writers. #7936 - WAL apply no longer pauses when partition compaction holds the table writer. #8194
Correctness fixes
This release fixes wrong results, crashes and hangs in RIGHT/FULL hash joins, SPLICE JOIN, WINDOW JOIN, set operations over geohashes, SAMPLE BY with month and year strides, LIMIT and FILL, and parallel filtered queries under concurrent load. It also fixes queries returning wrong rows during out-of-order ingestion, index scans on Parquet partitions, covering indexes returning NULLs after restore or column changes, materialized views after a base column type change, crashes and hangs when an out-of-order commit fails, and querying narrow DECIMAL columns over QWP.
Changelog
Features
- feat(sql): add GROUPING SETS, ROLLUP, CUBE support by @javier in #6853
- feat(core): breaking change 💥 - add row-level retention to materialized views by @nwoolmer in #7263
- feat(sql): breaking change 💥 - add DEDUP SKIP mode to keep existing rows on duplicate keys by @bluestreak01 in #7885
- feat(core): Introduce new
adaptivecommit mode by @nwoolmer in #7411
Performance
- perf(qwp): speed up QWP WebSocket ingestion of small messages by @jerrinot in #8110
- perf(core): treat async munmap as an eviction hint, revive released mappings by @ideoma in #7751
Fixes
- fix(sql): fix INSERT ... SELECT with a column list naming the wrong column in type errors by @eugenels in #7992
- fix(core): fix crash and hangs when an out-of-order commit fails by @bluestreak01 in #8063
- fix(http): fix client timeouts when following redirects by @jerrinot in #8084
- fix(sql): fix wrong SAMPLE BY results for month and year strides, LIMIT and mixed FILL by @puzpuzpuz in #8053
- fix(sql): fix wrong values in materialized views after a base column type change by @eugenels in #8039
- fix(sql): fix crashes and wrong results in RIGHT/FULL hash joins, SPLICE JOIN and keyed SAMPLE BY FILL by @ideoma in #8109
- fix(core): release native column files after converting a split active partition to Parquet by @RaphDal in #8065
- fix(core): fix queries returning wrong rows or failing during out-of-order ingestion by @jerrinot in #7935
- fix(core): fix covering index returning NULLs after restore and column changes by @ideoma in #8117
- fix(qwp): fix quiet QWP connections blocking WAL cleanup by @jerrinot in #7936
- fix(core): fix WAL apply pausing when partition compaction holds the table writer by @kafka1991 in #8194
- fix(core): fix wrong rows from index scans and conversions of parquet partitions by @ideoma in #7988
- fix(core): fix WAL apply falling back to slow 1-by-1 mode on backlogs with wide timestamp range by @ideoma in #8008
- fix(sql): fix wrong results and internal errors in WINDOW JOIN, set operations, SAMPLE BY FILL, string functions and UDP ingestion by @eugenels in #8001
- chore(qwp): breaking change 💥 - reject conflicting designated timestamps by @RaphDal in #8052
- fix(qwp): fix querying DECIMAL columns with precision up to 9 over QWP egress by @sklarsa in #8134
- fix(core): fix missing indexed rows after changing column types on Parquet tables by @ideoma in #8236
- fix(sql): fix SAMPLE BY FILL(LINEAR) returning NULL between large DOUBLE values by @eugenels in #8042
- fix(core): fix checkpoints of altered views and flaky cookie expiry tests by @glasstiger in #8248
- fix(core): fix parquet index repair and deduplication after upgrades by @ideoma in #8139
- fix(core): fix parallel queries hanging under concurrent load and skipping rows in batched PG Wire fetches by @kafka1991 in #8278
Full Changelog: 10.1.0...10.2.0
AI summary New SQL features and performance improvements
QuestDB 10.1.0
QuestDB 10.1.0 adds new SQL features, makes several query shapes faster, and fixes a large batch of correctness and reliability bugs. New SQL includes SUBSAMPLE for server-side downsampling, the percentile_disc / percentile_cont functions, right-hand filters in HORIZON JOIN, and audited views. Parallel GROUP BY now runs over hash joins, and LATEST ON, symbol LIKE/regex filters, SAMPLE BY ... TIME ZONE and out-of-order ingestion on XFS are faster.
This release contains several breaking changes. Read the Breaking changes section before you upgrade, especially if you use HORIZON JOIN, dateadd() timestamps, INT arithmetic, interval strings such as '1min', or Intel macOS.
For any questions or feedback, please join us on Slack or on Discourse.
See also our prettier release notes page.
Breaking changes 💥
HORIZON JOINwithout aggregates no longer de-duplicates its output. AddSELECT DISTINCTor an explicitGROUP BYto get the old result. Materialized views over such queries needREFRESH MATERIALIZED VIEW <name> FULL. #7682HORIZON JOINrejects unsupportedONpredicates with an error. Before this change, it ignored them. #7688- INT arithmetic wraps at 32 bits in every context, including under a 64-bit cast or on insert into a LONG column. To compute at 64 bits, widen an operand:
secs * 1_000_000Lori::long * j. This reverts #4824 and #7021. #7320 - Malformed intervals are rejected.
SAMPLE BY,timestamp_floor()and materialized viewREFRESHintervals must use a one-letter unit (1m,100T,1d). Before this change,'1min'was silently read as 1 nanosecond and'100ms'as 1 second. #7702 dateadd()projections keep a designated timestamp only for fixed-duration units over the designated timestamp itself. Time-series joins,SAMPLE BYand partitioned CTAS over otherdateadd()projections, such as month or year units, now fail to compile. Views that depend on them become invalid. Queries also no longer return an extra hiddenORDER BYcolumn. #7681subsampleis a reserved word. Quote existing identifiers with that name, e.g."subsample". #7013- Statements that would suspend a WAL table are rejected at compile time:
UPDATEon tables with Parquet partitions,ADD INDEXwith cold partitions, andALTER COLUMN TYPEwith read-only partitions. #7666 - Some partitioned CTAS over a multi-key
LATEST ONwith a covering index no longer infer the designated timestamp. SpecifyTIMESTAMP(col)explicitly. #7615 - Object visibility. In Enterprise, users no longer see tables and views they hold no permission on. In open source, a materialized or live view can no longer reach catalogue functions or
SHOWstatements through a regular view. #7687 - HTTP sessions end with their credentials. A request whose
Authorizationheader is rejected gets 401 and closes the session instead of falling back to the session cookie. #7799 - Bundled Java client:
sf_max_total_bytesnow caps a sender pool as a whole rather than each sender. #7736 - x86-64 (Intel) macOS is no longer supported. QuestDB no longer ships native binaries for that platform. #7555
Highlights
SUBSAMPLE: server-side downsampling
The new SUBSAMPLE clause cuts a time-series result down to a fixed number of representative rows before QuestDB sends it to the client. A chart can ask for as many points as it can draw instead of fetching millions of rows. Unlike SAMPLE BY, SUBSAMPLE returns original rows, not aggregates, so every column of a selected row is unchanged.
SELECT ... FROM ... [WHERE ...] [SAMPLE BY ...] SUBSAMPLE method(args) [ORDER BY ...] [LIMIT ...]
The methods are lttb, m4, minmax, uniform, cadence and sdt. Input size is capped by cairo.sql.subsample.max.rows (default 100,000,000). subsample is now a reserved word (see Breaking changes). #7013
New SQL capabilities
percentile_discandpercentile_contare now available as aggregates and as whole-partition window functions, withquantile_disc/quantile_contaliases. They also accept an array of percentiles and returnDOUBLE[], e.g.percentile_cont(price, ARRAY[0.5, 0.95, 0.99]).approx_percentilegains the same array form. As part of this change,approx_percentileandapprox_medianno longer return another group's value for empty groups. #6680HORIZON JOINsupports right-hand filters, either inON(ON (t.sym = q.sym AND q.venue = 'A')) or as a filtered subquery (HORIZON JOIN (quotes WHERE venue = 'A') q). The filter runs before ASOF matching, so each row matches the latest qualifying right-hand row. Before this change, non-keyONpredicates were silently ignored. #7688HORIZON JOINwithout aggregates returns one row per left-hand row and offset, and keeps the left-hand designated timestamp. #7682- Audited views and IN lists in
DECLARE. ADECLARE ... AUDITED @varmarks view parameters whose resolved values QuestDB Enterprise records on each read. A declared variable can now hold the list that anINfilter tests against. #7602 lag()/lead()work over SYMBOL columns. #7351
Faster queries and ingestion
- Parallel
GROUP BYover hash joins. AGROUP BY(or aSAMPLE BYrewritten to one) over an INNER, LEFT or eligible RIGHT equi-join now builds one shared hash table and joins and aggregates on the worker pool. In the PR's 4M-row ParquetLEFT JOINbenchmark, latency dropped from about 101 ms to 50 ms and peak memory from 308 MB to 165 MB. This is on by default;cairo.sql.parallel.hash.join.groupby.enabled=falseturns it off. #7618 LATEST ONis faster. Filtered and multi-symbolLATEST ONqueries ran 2.9-7.1x faster on the PR's benchmark. A key filter outside aLATEST ONsubquery is now pushed inside, so QuestDB finds the latest row only for the requested keys. #7655, #7615LIKE,ILIKEand regex filters on indexed SYMBOL columns can use the index, including the negated forms. Selective patterns ran 35-73x faster in the PR's benchmark. Broad patterns fall back to a scan.cairo.sql.symbol.pattern.index.enabledcontrols this. #7354- Calendar-aligned
SAMPLE BYwith a DST time zone runs up to about 65% faster for day buckets. #7706 - Out-of-order commits on XFS no longer wait on a synchronous disk write per column. In the PR's test,
posix_fallocatetime during WAL apply fell from 2,171 ms to 28 ms. #7795 - Fewer ingestion and query stalls from slow
munmap, which no longer runs while holding a process-wide lock. #7771 - Joins on SYMBOL keys use less memory. Their symbol translation caches moved off-heap and count toward the per-query memory limit. Some join shapes run slower: LT and two-key ASOF JOINs ran 1.16-1.22x slower, and HORIZON JOINs 1.46-1.51x slower, at the default
cairo.sql.join.symbol.translation.cache.capacity. #7650 CREATE TABLEwith many SYMBOL columns is faster innosynccommit mode. #7912- Worker fibers reduce GC pressure and resume latency for suspendable SQL and protocol work. #7379, #7561
Storage and operations
- Merge-append partitions (opt-in). With
cairo.o3.partition.merge.append.enabled, a backdated write into a cold partition appends the touched rows instead of rewriting the whole partition. This cuts O3 write amplification. The partition keeps superseded data as dead space until compaction reclaims it. The flag is off by default. Every non-read-only server now runs apartition-compactionworker, controlled bycairo.partition.compaction.check.interval(default 2 minutes; a negative value disables it). #7595 - Global metrics are persisted to
sys.metrics, a day-partitioned table with configurable sampling, TTL and exclusions.metrics.persist.enabledis on by default. #7634 - Retryable bounded shutdown. Embedders and deployment controllers can stop the server within a deadline, then retry. #7540
QWP, security and Web Console
- Browsers can connect to QWP over WebSocket, either same-origin with session-cookie authentication or cross-origin through the reloadable
qwp.browser.allowed.originsallowlist. Capability negotiation also works without custom headers. #7531, #7683 - Large QWP query results no longer crash the server. In a 50-million-row read, peak RSS fell from 6.40 GiB to 462 MiB. Rows left over from a cancelled query no longer reach the next query on the same connection. #7755
- ILP-over-HTTP authorizes each request as its own identity. Before this fix, a keep-alive connection could check later commits against the identity of the first writer. #7643
- Web Console 2.0.5 adds live views support, a query activity drawer, an option to run the full query text, and rule-based trends in the result grid. #7691
Correctness fixes
This release fixes wrong results, compile failures, hangs and crashes across HORIZON JOIN, WINDOW JOIN, SAMPLE BY (including FILL), ORDER BY, LATEST ON and dateadd() queries. It also fixes filters over UUID, IPv4, CHAR, SYMBOL and BOOLEAN columns, covering and posting indexes, parallel filtered scans, and materialized view refresh. Other fixes cover log writer hangs and failures, Parquet rewrites after a column type change, and resumed HTTP static file downloads. #7681, #7550, #7871, #7877, #7664, #7675, #7880
Changelog
Features
- feat(core): support retryable bounded shutdown by @kafka1991 in #7540
- feat(sql): accelerate LIKE/ILIKE/regex filters on indexed symbol columns by @nwoolmer in #7354
- feat(qwp): support browser negotiation and session authentication by @glasstiger in #7531
- feat(core): add query resource isolation primitives by @kafka1991 in #7585
- feat(sql): breaking change 💥 - add SUBSAMPLE clause for server-side downsampling; subsample becomes a reserved word by @javier in #7013
- feat(sql): restrict security-context functions in materialized and live views by @glasstiger in #7631
- feat(core): persist global metrics to sys.metrics by @ideoma in #7634
- feat(qwp): allow authenticated browser WebSockets by @glasstiger in #7683
- feat(sql): breaking change 💥 - support right-hand side filtering in HORIZON JOIN by @kafka1991 in #7688
- feat(sql): add audited views and IN lists in DECLARE variables by @nwoolmer in #7602
- feat(sql): breaking change 💥 - return one row per left-hand row and offset from HORIZON JOIN without aggregates by @bluestreak01 in #7682
- feat(core): add merge-append partitions to cut O3 write amplification by @ideoma in #7595
- feat(sql): add percentile_disc and percentile_cont aggregate and window functions, and fix approx_percentile and approx_median results for empty groups by @nwoolmer in #6680
- feat(sql): parallelize GROUP BY over hash joins by @puzpuzpuz in #7618
Performance
- perf(core): reduce GC pressure from suspendable workloads by @kafka1991 in #7379
- perf(core): reduce Fiber resume latency and improve execution locality by @kafka1991 in #7561
- perf(sql): breaking change 💥 - speed up latest-by queries with partition-key filters by @mtopolnik in #7615
- perf(sql): reduce memory used by joins on SYMBOL keys by @puzpuzpuz in #7650
- perf(sql): speed up calendar-aligned SAMPLE BY with a time zone by @puzpuzpuz in #7706
- perf(core): reduce ingestion and query stalls caused by slow file unmapping by @jerrinot in #7771
- perf(core): speed up applying out-of-order commits on XFS by @jerrinot in #7795
- perf(sql): speed up filtered and multi-symbol LATEST ON queries by @kafka1991 in #7655
- perf(core): skip per-symbol-column msync on CREATE TABLE in nosync mode, make async mmap sync a no-op by @ideoma in #7912
Fixes
- fix(sql): make INT arithmetic wrap consistently at 32 bits in every context by @puzpuzpuz in #7320
- fix(wal): prevent invalid symbol mappings by @kafka1991 in #7518
- fix(core): fix concurrent queue spuriously reporting empty under contention by @kafka1991 in #7557
- fix(sql): fix join filtering and Parquet pruning after conversion by @kafka1991 in #7541
- fix(core): prevent false live view invalidation during replica catch-up by @jovfer in #7543
- fix(sql): fix a parallel GROUP BY or horizon join failure being misreported as a timeout by @kafka1991 in #7581
- fix(core): prevent NULL covered values written after a posting index seal by @bluestreak01 in #7603
- fix(core): make live view registry publication and removal generation-aware by @bluestreak01 in #7609
- fix(wal): keep the _rebase_source marker through the dropped-table sweep by @ideoma in #7600
- fix(sql): fix wrong results and crashes in filters over UUID, IPv4, CHAR, SYMBOL and BOOLEAN columns, in covering indexes and on out-of-range nanosecond timestamps by @puzpuzpuz in #7550
- fix(sql): keep materialized views refreshing and clean up dropped-view timers by @puzpuzpuz in #7573
- fix(sql): fix covering index nulling included columns before their index by @ideoma in #7559
- fix(ilp): authorize ILP-over-HTTP inserts as the identity of each request by @glasstiger in #7643
- fix(sql): fix materialized view refresh retries on reader pool exhaustion by @bluestreak01 in #7669
- fix(sql): allow lag/lead over SYMBOL columns by @jerrinot in #7351
- fix(http): fix resumed static file downloads by @emrberk in #7652
- fix(sql): breaking change 💥 - reject UPDATE and schema changes that would suspend tables with parquet or cold partitions by @ideoma in #7666
- fix(core): fix posting index corruption on very large partitions by @jerrinot in #7664
- fix(sql): breaking change 💥 - reject malformed intervals like '1min' instead of silently misreading them by @jerrinot in #7702
- fix(core): fix instance hang when a log call fails mid-message by @ideoma in #7675
- chore(qwp): breaking change 💥 - make sf_max_total_bytes cap the whole sender pool and close sender connections cleanly - OSS tandem by @bluestreak01 in #7736
- fix(qwp): fix QWP query clients failing or reporting an invalid row count on TRUNCATE, SET and similar statements, and QWP senders timing out on close() by @bluestreak01 in #7770
- fix(sql): fix hangs, slowdowns and wrong counts in parallel filtered queries by @kafka1991 in #7871
- fix(sql): fix HORIZON JOIN overflow messages and missing RANGE offsets by @kafka1991 in #7902
- chore(core): breaking change 💥 - hide tables and views from users who cannot access them by @glasstiger in #7687
- fix(core): fix repeated parquet rewrites and misplaced column data after column type change by @ideoma in #7880
- fix(sql): breaking change 💥 - fix wrong results, failures, hangs and a crash in HORIZON JOIN, WINDOW JOIN, SAMPLE BY, ORDER BY and dateadd() queries by @puzpuzpuz in #7681
- fix(core): make rolling logs visible promptly and recover from log writer failures by @ideoma in #7640
- fix(sql): prevent EXPLAIN failures after compiler reuse by @kafka1991 in #7900
- fix(qwp): prevent crashes on large query results by @jerrinot in #7755
- fix(sql): fix SAMPLE BY FILL returning wrong rows when a column shares the timestamp name or an outer GROUP BY wraps the fill by @jovfer in #7877
- fix(core): breaking change 💥 - tie HTTP sessions to their credentials and stop reused JSON parsers growing their copy buffer - OSS tandem by @glasstiger in #7799
Platform
- build: drop x86-64 (Intel) macOS support and run macOS tests on Apple Silicon by @bluestreak01 in #7555
Web Console
Full Changelog: 10.0.1...10.1.0
QuestDB 10.0.1
QuestDB 10.0.1 is a maintenance release that builds on 10.0.0 with improvements across SQL, QWP, Live Views, DECIMAL, storage, and the Web Console. Expanded fuzz, fault-injection, and concurrency coverage strengthens a number of less-common execution and failure paths.
The release also improves high-cardinality window queries and Live View refreshes, streams eligible ordered UNION ALL queries without a full sort, reduces idle-worker allocation on JDK 24+, and bundles Web Console 2.0.3.
For any questions or feedback, please join us on Slack or on Discourse.
See also our prettier release notes page.
Highlights
Reliability and protocol hardening
- QWP table-update caching now follows table lifecycle and schema changes more closely, including
DROP/recreate, rename, and column-type changes. Durable acknowledgement accounting also covers transactions committed at the append-time row threshold. #7383, #7484 - Partition squash and POSTING-index lifecycle paths gain additional concurrency and I/O handling, improving behavior around open partitions, concurrent writers, and rollback. #7487, #7485, #7382
- Column type conversion now reports low-disk-space failures cleanly, and metadata compatibility improves for tables created before QuestDB 6.1. #7537, #7476
Faster and more capable windows and Live Views
Compatible window functions over the same PARTITION BY key can now share one map and one probe per row. The largest gains occur at high key cardinality: in the PR benchmark, a three-function bounded window over one million keys ran about 2.1x faster and retained 65 MiB less native memory on the cached path. The optimization is controlled by the reloadable cairo.sql.window.map.fusion.enabled setting. #7515
The same change substantially reduces Live View refresh, seal, restart, and transient-memory costs. In the reported 3.8-million-account benchmark, per-batch refresh fell from 4.43 seconds to 0.48 seconds and restart from 79.7 seconds to 3.86 seconds. Live Views can also project aliases and scalar expressions around window functions, with broader coverage for bounded RANGE frames, extreme timestamps, replay, and NOCACHE symbols.
Additional hardening makes view startup, routine base-table DDL, and concurrent refresh behavior more consistent. #7465, #7486, #7512
DECIMAL coverage and interoperability
Expanded DECIMAL coverage improves arithmetic and scale handling, NULL consistency, casts, bind variables, WAL replay, ILP, CSV import/export, Parquet filtering, and storage. #7452
ALTER TABLE ... ALTER COLUMN ... TYPE now converts between DECIMAL and FLOAT/DOUBLE in both directions. For Parquet-backed data, QuestDB converts the affected partitions to native format first.
SQL, protocols, and Web Console
- Ordered
UNION ALLcan stream through a merge operator instead of sorting. Eligible full scans ran about 8-9x faster in the PR benchmark, whileLIMITqueries can stop without materializing and sorting the full union. Branches must expose compatible designated timestamps and scan order. #7348 - An all-SYMBOL
UNIONorUNION ALLnow returnsSYMBOL. HTTP metadata and CTAS preserve the type instead of widening it to STRING; PGWire continues to expose both through the VARCHAR OID. #7397 - Scalar subqueries, indexed
LATEST ON, lateral aggregates, large GROUP BY maps, VARCHAR date parsing, andSHOW CREATE DATABASEsubqueries gain broader plan and edge-case coverage. #7388, #7481, #7432, #7434, #7417, #7384 - PGWire result framing now handles additional ARRAY, IPv4, and GEOHASH format combinations. ILP TCP authentication handling is more robust for malformed input, and
current_user()/session_user()report the authenticated principal. #7469, #7488, #7273 - Web Console 2.0.3 adds light/dark themes, notebook-level auto-refresh with per-cell overrides, improved grid sizing and editor settings, and OIDC and terminology fixes. #7458, #7533
Changelog
Features
- feat(sql): return SYMBOL from a UNION over symbol columns by @glasstiger in #7397
Performance
- perf(core): reduce GC pressure from idle workers on JDK 24+ by @kafka1991 in #7459
- perf(sql): speed up window queries and fix wrong results in windows and live views by @puzpuzpuz in #7515
- perf(sql): stream ordered UNION ALL without sorting by @brunocalza in #7348
Fixes
- fix(core): load view definitions before the engine publishes READY by @RaphDal in #7465
- fix(sql): fix scalar subquery predicates and timestamp interval pruning by @nwoolmer in #7388
- fix(core): fix crash when reading tables created before QuestDB 6.1 by @nwoolmer in #7476
- fix(pgwire): fix queries hanging until the connection times out by @jerrinot in #7469
- fix(sql): rebind bind variable in deferred indexed LATEST ON by @nwoolmer in #7481
- fix(sql): handle conservative ASCII hints in VARCHAR date parsing by @jerrinot in #7417
- fix(core): fix live views turning invalid after routine base table DDL by @bluestreak01 in #7486
- fix(qwp): reject oversized table counts by @jerrinot in #7493
- fix(core): fix covering-index reads on Windows by @glasstiger in #7499
- fix(ilp): stop ILP TCP authentication failures escaping as unhandled errors by @bluestreak01 in #7488
- fix(core): prevent invalid native-memory writes by @jerrinot in #7453
- chore(core): harden decimal type handling by @RaphDal in #7452
- fix(core): stop POSTING index close() truncating a region another writer published by @bluestreak01 in #7485
- fix(core): prevent false live view invalidation during concurrent refresh by @bluestreak01 in #7512
- fix(core): fix table suspension after a range replace removes its last partition by @puzpuzpuz in #7380
- fix(sql): fix NULL results for count expressions in LEFT JOIN LATERAL by @kafka1991 in #7432
- fix(core): signal restore cancellation promptly on shutdown by @jovfer in #7361
- fix(qwp): fix silent row loss after DROP in the qwpudp table-update cache by @nwoolmer in #7383
- fix(core): fix incorrect query results and premature memory-limit errors in large queries by @puzpuzpuz in #7434
- fix(core): stop partition squash losing var-column data on the open partition by @bluestreak01 in #7487
- fix(sql): fix filters on SHOW CREATE DATABASE subqueries by @nwoolmer in #7384
- fix(qwp): fix durable acks issued before the WAL upload is confirmed by @bluestreak01 in #7484
- fix(core): fix the web console showing "admin" instead of the authenticated user by @glasstiger in #7273
- fix(core): fix a POSTING index crash on rollback after a value-file I/O error by @puzpuzpuz in #7382
- fix(core): fix crash on column type conversion under low disk space by @ideoma in #7537
Web Console
- chore(ui): upgrade web console to 2.0.2 by @emrberk in #7458
- chore(ui): upgrade web console to 2.0.3 by @emrberk in #7533
Full Changelog: 10.0.0...10.0.1
QuestDB 10.0.0
QuestDB 10.0.0 is a major release, bringing three key new features into general availability, alongside a host of performance upgrades, bugfixes, and ergonomic improvements, that make QuestDB 10.0.0 easier than ever to build and scale with.
This release includes QWP, the QuestDB Wire Protocol, which supercedes ILP and PG Wire. The protocol is compressed binary, columnar, and pipelined over WebSockets, and should be used for both ingress and egress going forward, though the other protocols are retained for backwards compatibility. The new clients are smart, with the ability to buffer up data locally and automatically failover between your instances, helping to ensure ~0s RPO.
Live Views allow you to incrementally maintain and cache a window-function result set, with millisecond update latency. This cements QuestDB's already stellar performance for dashboarding and charting workflows, alongside the existing Materialized Views, which cover aggregations.
Web Console 2.0 is a significant overhaul to the QuestDB Web Console, bringing new Notebooks and coding-agent integration. The Notebooks feature offers Jupyter-style notebook support, for literate text, images, code, and live charts. MCP integration with your favourite coding agent helps you build trading dashboards and analyse data directly from your console.
But outside of the headline features, we've overhauled many internal mechanisms, and brought a host of performance improvements and bugfixes, making QuestDB 10.0 the most reliable version yet.
Read the release post: QuestDB 10.0: one binary protocol, in and out
For any questions or feedback, please join us on Slack or on Discourse.
See also our prettier release notes page.
Highlights
QWP: a new protocol for ingestion and queries
QWP — the QuestDB Wire Protocol — is new in 10.0.0. It is a binary, columnar protocol over WebSocket that carries both directions of your workload on one connection: rows in, results out. It runs on the existing HTTP port, so there is no new port to open and nothing to enable server-side. ILP and PG Wire are retained for backwards compatibility, but we recommend adopting QWP going forward.
One handle serves the whole deployment, pooling connections for both roles, and managing reconnection for you:
try (QuestDB db = QuestDB.connect("ws::addr=localhost:9000;")) {
    try (Sender sender = db.borrowSender()) {
        sender.table("trades").symbol("symbol", "ETH-USD")
              .doubleColumn("price", 2615.54).atNow();
    }
    try (Query q = db.borrowQuery()) {
        q.sql("SELECT price FROM trades WHERE symbol = $1")
                .binds(b -> b.setVarchar(0, "BTC-USD"))
                .handler(handler).submit().await();
    }
}
Fast ingress
ILP is a relatively inefficient protocol, sending key=value text pairs over the wire. Though we mitigated this for some data types (doubles, arrays) by sending binary values, the protocol was limiting and inflexible.
QWP instead sends fully-typed columns, with each frame of rows compressed before sending. A typical row when sent over QWP will take 3-4x less space when compared to ILP (TSBS schema).
Additionally, the protocol pipelines requests over WebSockets, meaning it can achieve tens of millions of rows/second on a single connection.
Fast egress
PG Wire has been our query protocol of choice for years, and we're still keeping it for compatibility purposes. However, the protocol itself has many edge cases, and is fundamentally row-oriented. This makes sense for an OLGP database like Postgres, but not for our time-series use case, where users frequently pull very large results set from the database.
QWP is also an query protocol, with unparalleled egress performance, achieving in excess of 200M rows/second, with first-batch latency of a handful of milliseconds. This includes native integration with Arrow/Polars/Pandas in the Python client, allowing you to run analysis externally without introducing latency.
Store-and-forward
When writing rows to a QWP Sender, the data is no longer ephemeral. The new store-and-forward mechanism buffers up data locally before streaming it to QuestDB. In the event of a network disconnect, the data is retained and replayed later.
Durability is an explicit choice: the default memory mode survives process restarts but not host power loss, sf_durability=periodic checkpoints to disk on a cadence, and request_durable_ack=on waits for the server to confirm durability end-to-end.
The client also supports smart failover; you can configure multiple addr endpoints, enable automated failover, and assign a priority to preferentially reconnect to the primary or to a replica.
The combination of these features makes it easy to achieve ~0s RPO on a QuestDB Enterprise deployment.
| Client | QWP status |
|---|---|
| Java, C/C++, Rust, Python | Full support |
| Go, .NET | Beta — most features, not full compatibility |
| Node.js | Coming in a later release |
Live Views (Beta)
A Live View incrementally maintains a window function result set, with WAL-table backing for durability. This complements the existing Materialized Views, which store aggregate results, but brings a new in-memory tier, allowing for millisecond-tier update latencies.
This closes a gap for charting and dashboarding use cases, making it easier than ever to run analysis and trading indicators that scale gracefully as your dataset grows.
CREATE LIVE VIEW trades_ma
FLUSH EVERY 1s
IN MEMORY 5s
START FROM NOW
AS
SELECT timestamp, symbol, price,
       avg(price) OVER (
           PARTITION BY symbol
           ORDER BY timestamp
           ROWS 300 PRECEDING
       ) AS moving_avg
FROM trades;
Refresh and flush are decoupled, which is what keeps reads fresh without paying for a write per row. Computed rows land in an in-memory tier immediately; FLUSH EVERY controls when they are persisted to the view's own WAL. A SELECT sees the un-flushed lead, so freshness tracks base-apply latency rather than the flush cadence. IN MEMORY sizes how much recent output stays resident.
START FROM decides what the view contains, and is mandatory because the two ends differ by orders of magnitude. NOW resolves the create-time instant and costs almost nothing; BEGINNING seeds from the base table's whole history; an explicit timestamp literal starts from a point you choose. Membership is decided by a row's designated timestamp, not by when it was committed, so the view's contents are the same whether or not a replay has happened.
Anchored windows cover the other common shape — a cumulative aggregate that resets on a boundary, which is what daily PnL, month-to-date volume, or average price since the open actually need:
CREATE LIVE VIEW IF NOT EXISTS core_price_lv
FLUSH EVERY 5s IN MEMORY 5s START FROM NOW
AS SELECT timestamp, symbol, bid_price,
          avg(bid_price) OVER w AS moving_avg
FROM core_price
WINDOW w AS (
    PARTITION BY symbol
    ORDER BY timestamp
    ANCHOR DAILY '00:00'
);
ANCHOR DAILY '00:00' resets each partition's aggregate at midnight UTC; add an IANA time zone when the boundary should follow local civil time.
Start with the live views concept page and CREATE LIVE VIEW.
Web Console 2.0: notebooks and coding agents
The bundled Web Console moves to 2.0, and the headline addition is notebooks: a saved document of SQL cells, each rendering as a grid or a chart, that you build up and re-run instead of keeping a scratch query around.
- Cells have a view toggle and an auto-refresh interval, so a notebook doubles as a live dashboard.
- A coding agent can author and edit cells for you, including edits that run in the background while you keep working. QuestDB's MCP server exposes your instance to agents outside the console too.
- Large notebooks stay responsive — charts, grids and editors are virtualized, and cells lazy-hydrate.
Outside notebooks: the result grid is now a shared ResultGrid component, cancelling a running query is reliable and preserves your selection, and the console recognises the TO REMOTE storage-policy stage. #7317, #7420
Breaking changes 💥
SHOW PARTITIONSgains two trailing columns,seqTxn(index 16) andisRemotelyServed(index 17). Tools that bind result columns by position need updating. #6985pg_class.relkindandinformation_schema.tables.table_typenow report per object kind. This aligns the catalogue with PostgreSQL semantics. #7461circuit.breaker.buffer.sizeandnet.test.connection.buffer.sizeare obsolete. A config carrying them logs an advisory at startup, or fails underconfig.validation.strict. #7372EXPLAINover HTTP and CSV returns plain text./execand/expno longer HTML-escape the plan. Clients that un-escape the plan need updating. #7406- RANGE window frame bounds that overflow the designated timestamp's unit are rejected at compile time instead of silently wrapping onto a frame nobody wrote — e.g.
RANGE 300000 DAY PRECEDINGon aTIMESTAMP_NScolumn. The same guard coversWINDOW JOINbounds. #7461 IS NULLrow-group pruning is disabled forCHAR,FLOATandDOUBLEParquet columns #7461- Query cancellation, timeouts and client disconnect are now honoured everywhere. #7250, #7372
SUSPEND WALno longer requires dev mode, andSUSPEND/RESUME WALshare one authorization. #7239- QWP wire: a gapped delta symbol dictionary is rejected with a new status byte,
STATUS_DICTIONARY_GAP(0x0D), and deterministic ingest rejections are reported as terminal rather than retriable. The bundled client moves in lockstep. #7374, #7359 - Parquet output changes for external readers: file-level
column_ordersis declared, nested-array list elements are named canonically (element), andSTRING/SYMBOL/VARCHARmin/max statistics are bounded to 64 bytes and marked inexact. Bounds stay conservative supersets. #7283 SecurityContextgains two abstract methods (authorizeLiveViewCreate,authorizeLiveViewDrop). Implementations outside this repository must supply them. #7461
Other key changes
SHOW CREATE DATABASE
- A schema-only logical dump, the QuestDB equivalent of
pg_dump --schema-only— one round-trippable statement per row. Realpg_dumpcannot run against QuestDB, since thepg_*catalogs are empty and QuestDB DDL has no Postgres equivalent. - Filter with
INCLUDE/EXCLUDEoverTABLES,VIEWS,MATERIALIZED_VIEWS,SCHEMAandALL. Objects are emitted in an order that always replays, and re-dumps are byte-idempotent — useful for diffing schema snapshots in CI. - Safe against a live database: an object dropped or renamed mid-dump is skipped rather than aborting the statement. Enterprise extends the categories to ACL objects. Docs · #7232
Per-query memory limits
A runaway query, mat view refresh or WAL apply batch could previously drive the server toward OOM with only the process-wide RSS limit as a backstop, which kills whichever allocation crosses the line rather than the workload responsible.
- Three independent caps,
cairo.query.memory.limit.bytes,cairo.mat.view.refresh.memory.limit.bytesandcairo.wal.apply.memory.limit.bytes. Opt-in, default0, and reloadable viareload_config()— so start generous and tighten. - Watch usage through the new
memory_used/memory_limitcolumns onquery_activity(). A breach throws withisOutOfMemory()set and a distinctquery memory limit exceeded [workload=...]message. - It is a guard, not a guarantee. Two allocators stay on the global counter only: the vectorized (Rosti) keyed GROUP BY tables — the default plan for
SELECT key, sum(x) FROM t— andCOPY ... TOParquet export. #7184
Column type conversion on Parquet partitions
ALTER TABLE ... ALTER COLUMN ... TYPEnow works on Parquet-partitioned tables. It previously either failed or silently left the data unconverted, so reads returned the old type — or NULL after an O3 merge.- The ALTER is fast; the cost moves to reads. Partitions are not rewritten, and conversion happens lazily with a one-time decode per row group. Conversions involving
SYMBOLare the exception and eagerly convert affected partitions to native first. Results match the native path exactly. #7024
WAL suspension controls and REBASE WAL
- Hard-suspend a table out of circulation with
cairo.wal.apply.suspended.tablesandcairo.wal.apply.suspended.write.denied— both reloadable. WAL transactions are never applied and writes are rejected rather than queued, giving you a quiescent table. - Non-structural ALTERs and
FORCE DROP PARTITIONstill apply, through the WAL-bypass path. These bypass the sequencer, so they are not propagated to replicas. ALTER TABLE ... REBASE WALrebuilds a table under a fresh sequencer, keeping all applied data, for a transaction log that has grown enormous or gone corrupt. It requires hard suspension first, discards pending unapplied WAL, mints a newtableId, and invalidates dependent materialized views (recover withREFRESH ... FULL). #7239
Parquet interoperability with Iceberg, Spark, DuckDB and Trino
Fourteen fixes to how QuestDB's Parquet output reads in external tooling. Files written by older versions keep their old metadata until next rewritten, so re-export anything you want these to apply to. #7283
- Predicate pushdown starts working — QuestDB wrote per-row-group min/max but omitted the file-level
column_ordersdeclaration, without which the spec leaves min/max undefined, so readers skipped pushdown and PyIcebergadd_filesdropped the file into a null partition. - PyIceberg stops raising
KeyErroron nested arrays, which named the outer LIST elementlistrather than the canonicalelement; and columns stop being mis-mapped in Iceberg tables, where QuestDB'sfield_idcollided with Iceberg's own. - arrow-rs
with_page_index(true)stops failing the read — O3 merge-rewrite and append emitted no page index, leaving partitions partially indexed, which fails withmissing offset index. Timestampboundary_orderis now declared too, so readers can binary-search it. See the Parquet concept page.
New SQL
kurtosis()andskewness(), with_sampand_popvariants. One-pass Pébay algorithm over running central moments, so they merge across partials and run on the parallel GROUP BY path. #7221- Scalar sub-queries in comparison predicates —
WHERE price > (SELECT avg(price) FROM trades WHERE timestamp IN today()).<,>and=are implemented directly and the rest derived, including the swapped form. The sub-query runs once per query execution, and integers compare at 64 bits rather than throughdouble. #7377 wait_wal_table()andsleep()are production functions.wait_wal_table('trades')blocks until the WAL writer has applied up to a targetseq_txn— what you want before a read that depends on a prior write. Neither holds a worker thread while parked. #7031
Performance
- Sorting by text, UUID or LONG256 columns is much faster. The radix-based encoded sort used to engage only for fixed-width keys fitting 32 bytes; everything else fell back to a red-black tree. It now covers VARCHAR, STRING, SYMBOL, UUID, LONG256, LONG128 and wide multi-column keys, across full sorts and both serial and parallel top-K. On ClickBench
hits,ORDER BY SearchPhrase LIMIT 10goes 52 ms → 37 ms. #7242 - Filters that wrap the timestamp in a function now prune partitions.
WHERE date_trunc('day', ts) >= '...'orWHERE dateadd('h', 1, ts) < now()used to read the whole table; they now narrow the scan the way a plain timestamp filter does, by inverting the monotonic function back onto the timestamp axis. Where the inverse is exact the row filter is dropped entirely; where it is a sound superset it prunes and keeps a residual. #7305 - Expressions that are the same for every row are computed once per query instead of once per row — anything like
dateadd('d', -30, to_timezone(now(), 'Asia/Kolkata'))inside aCASEor a filter.EXPLAINoutput is unchanged. #7280 wait_wal_table()andsleep()no longer hold a worker thread while they wait, so far more can run at once than the worker pool size. #7031- Cached parallel aggregations and joins use less memory. Per-worker row-id lists under a JIT filter were pre-sized to the full page frame — up to 8 MB each — and held at peak until cache eviction. Teardown now returns them to initial capacity. #7267
- Checkpoint and snapshot restore is faster for tables with many Parquet partitions, verifying each
_pmsidecar once instead of up to three times and validating partitions in parallel. Native index rebuild also parallelizes across (partition, column) pairs. #7255
Changelog
Features
- feat(sql): add live views by @ideoma in #7461
- feat(qwp): stop resending the full symbol dictionary on every message by @glasstiger in #7374
- feat(qwp): add a connect timeout and tolerant client startup by @bluestreak01 in #7341
- feat(qwp): add per-query SYMBOL dict reset flag by @kafka1991 in #7321
- feat(core): add per-query memory limits by @puzpuzpuz in #7184
- feat(wal): add WAL-apply suspension controls and ALTER TABLE REBASE WAL by @ideoma in #7239
- feat(core): support column type conversions with parquet partitions by @ideoma in #7024
- feat(sql): parallel covered-index decode for aggregation and filter by @nwoolmer in #7284
- feat(sql): fast-lag append for covering-indexed WAL block-apply by @nwoolmer in #7414
- feat(sql): add SHOW CREATE DATABASE for schema-only dumps by @nwoolmer in #7232
- feat(sql): compare a numeric column with a scalar sub-query in predicates by @bluestreak01 in #7377
- feat(sql): add kurtosis and skewness aggregates by @brunocalza in #7221
Performance
- perf(sql): speed up ORDER BY on varchar, UUIDs and wide multi-column keys by @kafka1991 in #7242
- perf(sql): speed up filters that wrap the designated timestamp in a function by @kafka1991 in #7305
- perf(sql): evaluate runtime-constant subexpressions once per query instead of per row by @puzpuzpuz in #7280
- perf(sql): reduce memory footprint of cached parallel aggregations and joins by @puzpuzpuz in #7267
- perf(core): speed up checkpoint/snapshot restore for tables with many parquet partitions by @bluestreak01 in #7255
- perf(core): make wait_wal_table(), sleep() functions lightweight and not block IO threads by @ideoma in #7031
Fixes
- fix(core): regenerate _pm when restored data.parquet exceeds the committed size by @bluestreak01 in #7269
- fix(qwp-ws): fix flushAndGetSequence() returning a stale FSN after an empty flush by @adi1719 in #7257
- fix(core): prevent posting index out-of-memory during seal and rollback on skewed symbols by @nwoolmer in #7236
- chore(core): prevent a JVM crash when an async writer command races a writer close by @RaphDal in #7266
- fix(sql): fix crash on incomplete expression after CASE ... END by @mtopolnik in #7290
- chore(core): allow ADD INDEX over a parquet partition where the column is absent by @RaphDal in #7291
- fix(core): fix table corruption when a range-replace commit adds partitions above the last one by @puzpuzpuz in #7289
- fix(sql): fix wrong SAMPLE BY first()/last() results when the time column is not selected by @ideoma in #7282
- fix(sql): add cursor self-consistency checks and fault injection to query fuzzer and harden query engine by @puzpuzpuz in #7217
- fix(core): fix out-of-order rows after a lag commit crosses a partition boundary by @brunocalza in #7285
- fix(sql): concurrent NPE in CoveringIndexRecordCursorFactory.getCursor (#7294) by @bluestreak01 in #7298
- fix(sql): fix internal error when subtracting a literal from a timestamp by @puzpuzpuz in #7304
- fix(core): fix O3 lag commit recording maxTimestamp below the committed max across partitions by @bluestreak01 in #7297
- chore(core): stop truncating the
_pmsidecar on a rolled-back partition update by @RaphDal in #7268 - chore(core): fix native memory leak when a sharded parallel GROUP BY trips the per-query memory limit by @RaphDal in #7309
- fix(sql): fix wrong results from queries on renamed Parquet columns by @bluestreak01 in #7318
- fix(sql): honor query cancellation and timeouts in all query types by @bluestreak01 in #7250
- fix(core): RSS pre-flight the covered-sidecar snapshot in incremental posting seal by @nwoolmer in #7308
- chore(core): prevent table suspension on out-of-order inserts into parquet partitions by @RaphDal in #7310
- fix(core): fix spurious table metadata reload failures by @kafka1991 in #7312
- chore(sql): keep the per-query memory tracker balanced across aggregate re-execution by @RaphDal in #7319
- chore(core): refresh materialized views correctly after a base-table truncate and on read-only nodes by @jovfer in #7315
- fix(core): retry mat view refresh on transient errors instead of invalidating by @bluestreak01 in #7275
- chore(core): fix file-descriptor leak when the server shuts down with a query parked by @RaphDal in #7324
- fix(sql): avoid intermediate overflow in corr() denominator by @jovfer in #7313
- fix(http): prevent HTTP context reuse crashes and tighten multipart upload parsing by @jerrinot in #7327
- fix(sql): fix view reads failing due to incomplete dependency tracking by @glasstiger in #7322
- fix(core): fix query cancellation being lost when it races query startup by @jovfer in #7329
- fix(core): fix POSTING-indexed tables suspending WAL apply after out-of-order writes by @RaphDal in #7332
- fix(core): make DataID publication thread-safe by @bluestreak01 in #7344
- fix(core): prevent posting index corruption when .pk stat fails during column rename by @bluestreak01 in #7347
- fix(sql): fix crash joining or grouping on empty VARCHAR values by @sklarsa in #7346
- chore(core): improve Parquet interoperability with external readers and Iceberg tooling by @RaphDal in #7283
- fix(sql): fix LATEST ON returning the wrong row with an indexed key and residual filter by @nwoolmer in #7334
- fix(qwp): fail fast on deterministic ingest rejections instead of retrying them by @kafka1991 in #7359
- fix(qwp): prevent stale egress plans from leaking to clients by @jerrinot in #7350
- chore(core): fix catalogue queries omitting tables after a concurrent metadata cache clear by @RaphDal in #7360
- fix(sql): fix PIVOT and expression column names that embed double quotes by @glasstiger in #7353
- chore(core): fix socket leaks on shutdown when queries are parked or retrying by @RaphDal in #7368
- chore(core): resolve column files by writer index when converting a partition to Parquet by @RaphDal in #7363
- fix(core): fix POSTING index covering scans failing when queries migrate across worker threads by @nwoolmer in #7349
- chore(core): fix adding a covering index over parquet after a column type change by @kafka1991 in #7370
- fix(sql): clarify materialized view error when timestamp lacks a sampling interval by @Socialpranker in #7376
- fix(sql): fix cancel_query() spuriously cancelling the wrong query by @jerrinot in #7238
- fix(sql): fix dot_product returning wrong result for transposed arrays by @raphaelroshan in #7392
- fix(SQL): fix SAMPLE BY w to accept the week unit without a leading digit by @nabeel001 in #7391
- fix(http): return EXPLAIN plans as plain text by @emrberk in #7406
- fix(core): fix POSTING-indexed WAL table suspending after a partition squash by @ideoma in #7386
- fix(core): stop a query when its client disconnects by @kafka1991 in #7372
- fix(sql): fix NULL array handling, IPv4 aggregates, and parallel OOM handling by @puzpuzpuz in #7371
- chore(qwp): carry crash-safe SF cleanup and pool-capacity recovery by @bluestreak01 in #7387
- fix(core): fix covering index reading NULL after converting a parquet partition back to native by @nwoolmer in #7415
- fix(qwp): fix duplicate writes and store-and-forward recovery during failover by @bluestreak01 in #7366
- fix(sql): prevent JIT STRING null checks from crashing the server by @jerrinot in #7454
- chore(qwp): bump symbol dictionary limit to 2m by @ideoma in #7468
Build, CI and internals
- build: 9.4.3 by @bluestreak01 in #7265
- build(deps): bump js-yaml from 4.1.0 to 4.2.0 in /compat/src/test/nodejs-pg by @dependabot[bot] in #7271
- build(deps): bump js-yaml from 4.1.0 to 4.2.0 in /compat/src/test/nodejs-postgres by @dependabot[bot] in #7272
- ci(build): auto-detect SNAPSHOT client and enable local-client profile in release builds by @bluestreak01 in #7274
- chore(build): migrate GitHub Actions workflows off the deprecated Node 20 runtime by @RaphDal in #7277
- chore(core): format code with IDEA 2026.1.3 by @RaphDal in #7281
- ci(build): route Maven builds through the self-hosted Reposilite cache by @sklarsa in #7286
- ci(build): retry Maven wagon transfers on cache connect failure by @sklarsa in #7287
- test(core): de-flake HTTP export file-descriptor leak checks by @RaphDal in #7292
- test(core): stop posting-index fuzz from mixing replace commits with Parquet by @bluestreak01 in #7299
- test(core): stabilize flaky QWP credit-flow and worker-pool CI tests by @puzpuzpuz in #7306
- chore(qwp): exercise e2e test on the client changes by @bluestreak01 in #7307
- ci(build): bound cache connect timeout and retry connect failures by @sklarsa in #7311
- test(qwp): adapt facade E2E tests to the WebSocket-only client by @mtopolnik in #7314
- chore(ui): upgrade web console to 2.0.0 by @emrberk in #7317
- test(core): stop ServerMainForeignTableTest SAMPLE BY assertions flaking on the RSS check by @jovfer in #7323
- test(core): stop SampleByConfigTest flaking on the post-close RSS check by @RaphDal in #7325
- test(qwp): speed up sender coercion-error tests by @RaphDal in #7364
- ci(build): re-add docker image vulnerability scanning to release pipeline by @sklarsa in #7365
- chore(build): bump gosu to 1.19-go1.25.11 by @sklarsa in #7367
- test(core): fix seed-dependent crash in checkpoint fuzz test by @jovfer in #7381
- test(core): stop query_activity churn test hanging and cascading on constrained CI by @kafka1991 in #7395
- test(core): stop fuzz tests spuriously failing when logging non-ASCII index values by @RaphDal in #7396
- chore(build): bump gosu to 1.19-go1.25.12 by @questdb-maven-release-app[bot] in #7398
- ci(build): reduce Ubuntu package download failures by @bluestreak01 in #7405
- refactor(qwp): rename sf_max_bytes to sf_max_segment_bytes in e2e fuzz test by @mtopolnik in #7413
- chore(ui): upgrade web console to 2.0.1 by @emrberk in #7420
- test(sql): extend ASOF/LT JOIN fuzz coverage to multi-column ON clauses by @jerrinot in #6638
- test(qwp): assert proper treatment of empty and NULL arrays on egress by @mtopolnik in #7276
- chore(core): add new ent config key to server.conf template by @glasstiger in #7270
- chore(core): fix wrong symbol values on replicas after a column type conversion - fuzz test fix by @glasstiger in #7179
- chore(core): engine seams for hot in-place primary/replica role switch by @jovfer in #7261
- chore(core): pluggable WAL event types and partition flag bit by @RaphDal in #6985
New Contributors
- @adi1719 made their first contribution in #7257
- @Socialpranker made their first contribution in #7376
- @raphaelroshan made their first contribution in #7392
- @nabeel001 made their first contribution in #7391
- @questdb-maven-release-app[bot] made their first contribution in #7398
Full Changelog: 9.4.3...10.0.0
QuestDB 9.4.3
QuestDB 9.4.3 brings some key bug-fixes, along with parquet-native tables and new parquet-querying performance enhancements, with order-of-magnitude speedups for ORDER BY ... LIMIT queries.
For any questions or feedback, please join us on Slack or on Discourse.
See also our prettier release notes page.
Breaking changes 💥
- Two-bound
LIMIT nullsemantics changed, aligningLIMIT lo, hiwithLIMIT n:LIMIT null, nnow returns the first N rows (previously the full sorted set)LIMIT n, nullnow returns the empty result (previously all rows).LIMIT nullis unchanged, and returns the full result set.
EXPLAINplan output rewording for encodable sorts:- There was inconsistency in the rendering for 'encoding sorts'; this plan node will now render consistently as
Encode sort light. - If you assert any particular query plan shapes in your regression suite, you will need to update the assertions.
- There was inconsistency in the rendering for 'encoding sorts'; this plan node will now render consistently as
Highlights
Table-level Parquet format
Tables can now store partitions in PARQUET format by default, rather than only NATIVE. Previously, you would need to:
- Run
ALTER TABLE ... CONVERT PARTITION ... TO PARQUETqueries to synchronously convert partitions in QuestDB OSS. - Enable
STORAGE POLICYto asynchronously convert partitions in QuestDB Enterprise.
CREATE TABLE trades (ts TIMESTAMP, price DOUBLE, sym SYMBOL)
TIMESTAMP(ts) PARTITION BY DAY FORMAT PARQUET WAL;

ALTER TABLE trades SET FORMAT PARQUET;
ALTER TABLE trades SET FORMAT NATIVE;
Please note that:
FORMAT PARQUETcan only be set on partitioned write-ahead-log (WAL) tables.- When applying
FORMAT PARQUETviaALTER TABLE, historical partitions will not be automatically converted. FORMAT NATIVEremains the default format for tables in QuestDB.- Out-of-order writes are more expensive when applied to parquet partitions.
Memory-budgeted Parquet decode cache
There is a fine balance of memory budget versus CPU time when scanning and decoding parquet row groups. A fixed number of decode slots was an inflexible way to balance these two concerns.
Therefore, we have introduced a new memory-budget configuration and deprecated the old slot-based config:
- New:
cairo.sql.parquet.cache.memory.size- This is a per-cursor byte budget for decoded row groups (default 256 MB).
- Deprecated:
cairo.sql.parquet.frame.cache.capacity- This is still accepted, but not used.
Faster ORDER BY ... LIMIT N
The query engine has a number of optimisations based on the native-format data layout. We've revised the long top-K query path for parquet partitions, by removing a sorting tree and pruning projected columns earlier in the process. This is most valuable for queries over wide tables, with a significant sort plus limit workload.
This dramatically reduces unnecessary row-group decoding, and thus improves the scalability of this query shape for larger limits:

Concurrent ILP/TCP stale-writes fix
ILP/TCP is a mostly-deprecated ingestion path, though maintained for backwards compatibility. As part of this maintenance, we have fixed a bug which could cause stale data to be written to a table, affecting DECIMAL, LONG256 and implicit casts from BINARY to SYMBOL. This only impacted concurrent writes, so a straightforward single worker TCP stream was unaffected.
Thank you to our users who continue to use this feature and give us valuable feedback that helps us to keep it well-maintained.
With the upcoming QuestDB 10.0 release, we recommend planning an upgrade to our new ingestion API, which brings dramatically better performance and usability across the board.
Changelog
Features
- feat(sql): add
is_end_of_monthSQL function by @Dracylfrr in #7214 - feat(core): add periodic memory usage logging by @jerrinot in #7042
- feat(core): support parquet format table level by @ideoma in #7107
- feat(sql): add a memory-budgeted cache for Parquet random access by @puzpuzpuz in #7230
Performance
- perf(sql): speed up ORDER BY ... LIMIT N queries by @kafka1991 in #7222
- perf(sql): speed up parallel ORDER BY ... LIMIT N queries with encoded sort keys by @kafka1991 in #7241
- perf(sql): skip parquet decoding of rows that LIMIT discards by @kafka1991 in #7215
- perf(sql): push down filters into joins wrapped in views and subqueries by @ideoma in #7244
- perf(parquet): speed up partition-to-parquet conversion and reduce file size by @RaphDal in #7206
Fixes
- fix(sql): fix internal error when a dotted name follows an operator by @bluestreak01 in #7260
- fix(core): fix NATIVE_INDEX_READER leak when a posting-index row cursor is closed after its reader by @bluestreak01 in #7256
- fix(sql): fix wrong results in splice, right and full outer joins with a left-table filter by @puzpuzpuz in #7225
- fix(core): fix unexpected logout during HTTP session rotation by @brunocalza in #7249
- fix(sql): fix internal error when an IN subquery contains a join, and handle declared variables in join ON clauses by @puzpuzpuz in #7211
- fix(core): fix snapshot restore accepting truncated parquet partitions when _pm sidecar exists by @bluestreak01 in #7243
- fix(core): fix POSTING-indexed symbol queries returning wrong rows or crashing by @bluestreak01 in #7253
- fix(wal): fix symbol value corruption when skipping replaced transactions across DDL by @jovfer in #7248
- fix(core): fix Parquet crashes on malformed files and data corruption on partial reads by @glasstiger in #7223
- fix(ilp): fix data corruption in concurrent ILP over TCP by @jerrinot in #7240
- fix(sql): fix wrong first/last results in parallel GROUP BY by @ideoma in #7224
- fix(core): fix posting index crash and wrong covered reads after rollback by @bluestreak01 in #7229
- fix(qwp): fix unresponsive network I/O under heavy QWP ingestion by @jerrinot in #7231
- fix(core): fix crash and native memory overrun in covering index out-of-order commits by @bluestreak01 in #7227
Full Changelog: 9.4.2...9.4.3
@ Every self-hosted release, weekly
One Monday email with the week's stable releases across the directory.
More in Time Series
 Super ProductivityFree, open-source, local-first to-do app with timeboxing, time tracking, planner and Kanban boards; self-host the web app via Docker or SuperSync.
- tdengineSelf-hosted open-source time-series database for IoT and industrial data, offering clustering, stream processing, subscriptions, TDgpt AI and Grafana or Kafka links.
 TelegrafOpen-source, self-hosted telemetry agent that collects, processes and writes metrics and logs via 300+ plugins, shipped as a single static binary configured in TOML.
 timescaleTimescaleDB is an open-source, self-hosted PostgreSQL extension for time-series and event data, with hypertables, columnar compression, and continuous aggregates.
 victoriametricsOpen-source, self-hosted time series database and monitoring backend that replaces Prometheus or Graphite as Grafana's metrics store, with PromQL and MetricsQL querying.
- ArcadeDBOpen-source, self-hosted multi-model database: one ACID engine for graph, document, key-value, vector, full-text and time-series data, queried in SQL, Cypher or Gremlin.
 cratedbA self-hosted, open-source distributed SQL database with PostgreSQL wire protocol support, for real-time analytics over time-series, full-text and vector data.
 EmoncmsOpen-source app that ingests, logs and charts energy, temperature and environmental readings; self-hosted free via Docker or EmonScripts, from OpenEnergyMonitor.
 GrafanaMimirOpen-source, self-hosted long-term TSDB for Prometheus: multi-tenant, replicated metrics storage that scales past a billion active series.
 greptimedbSelf-hosted and open-source: one Rust columnar telemetry store keeps metrics, logs and traces in a single engine with SQL or PromQL queries over object storage.
 influxdbOpen-source, single-node time series database you self-host for real-time metrics and events, querying Parquet-backed data with SQL or InfluxQL.
0 comments