Self-host data-observability-installer
latestInstaller for self-hosted data observability and quality
- Stars
- 143
- CPU
- 2 CPUs
- RAM
- 8 GB
- Storage
- 20 GB
- Ports
- 8501 (TestGen UI), 8530 (TestGen API/MCP), 8082 (Observability UI)
What is data-observability-installer?
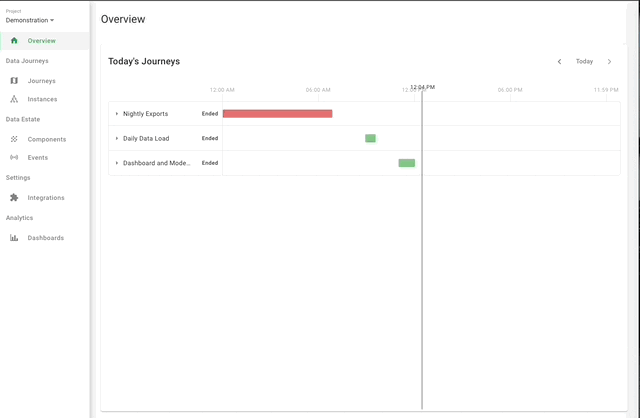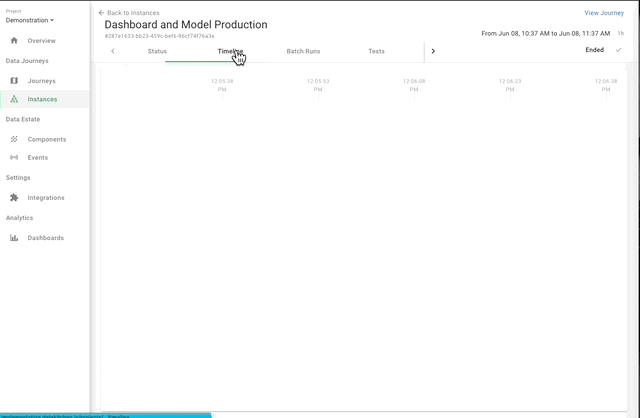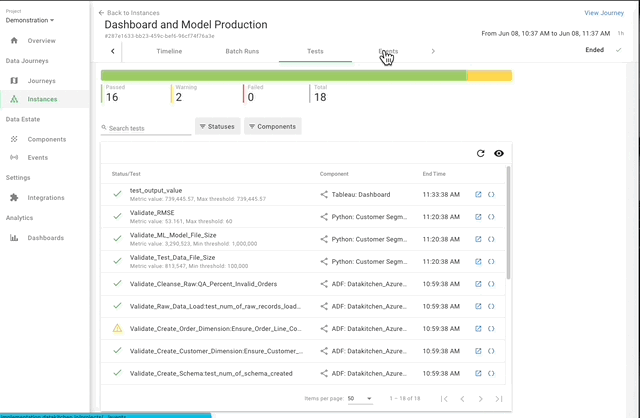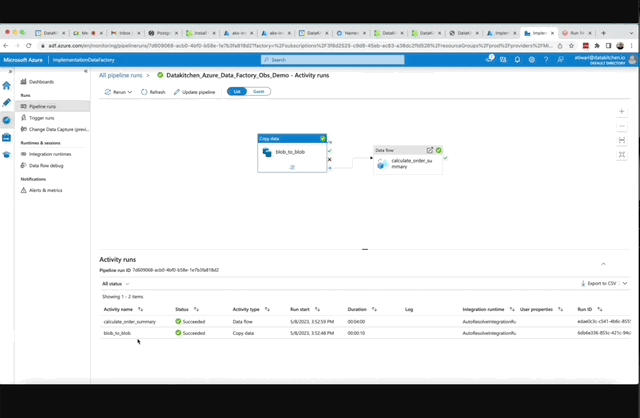
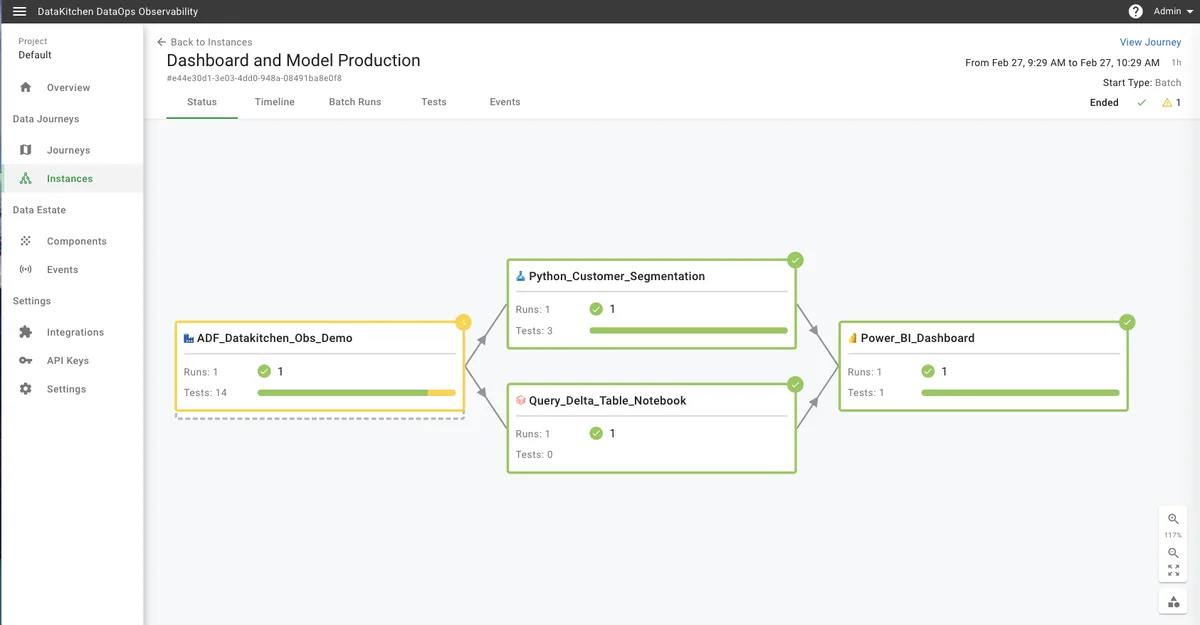
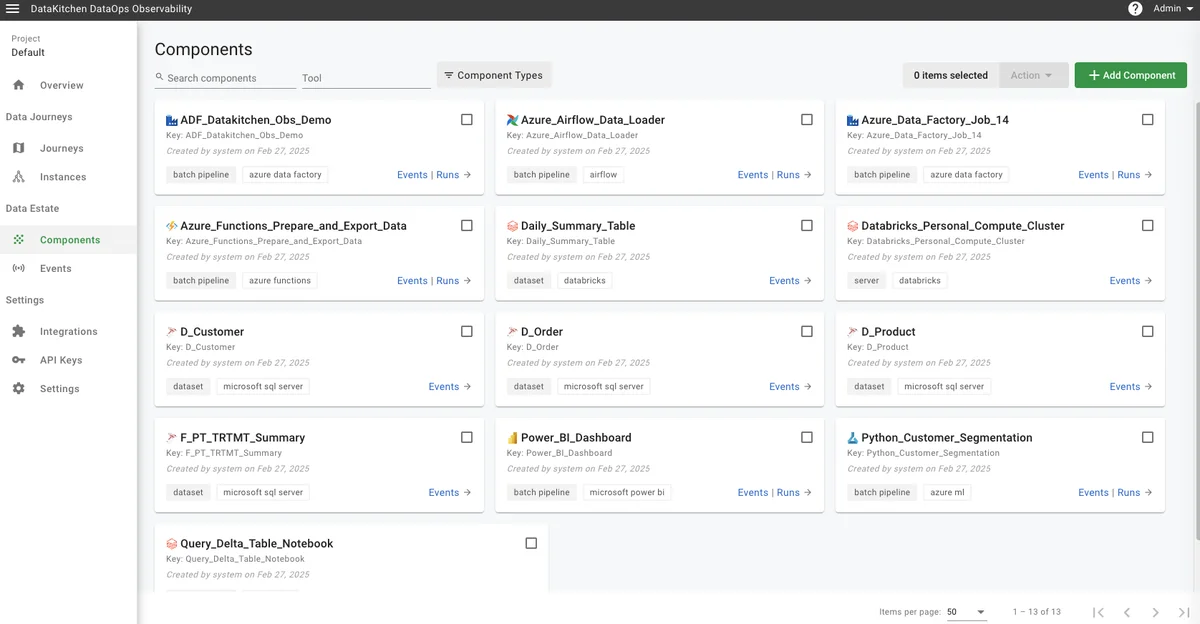
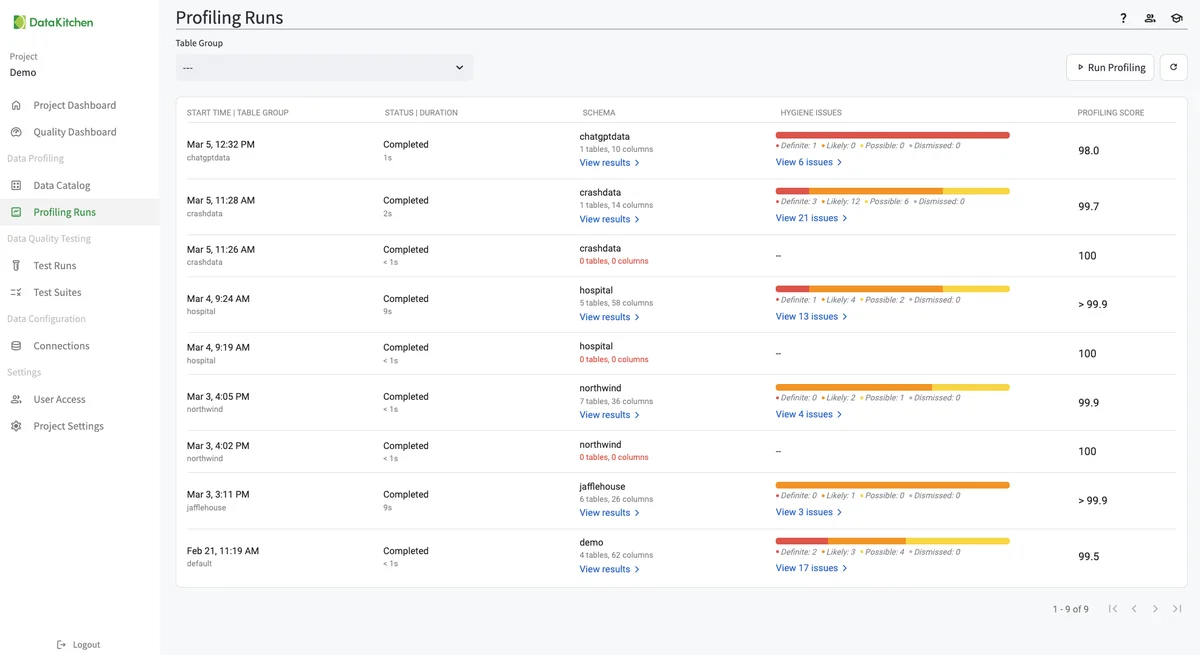
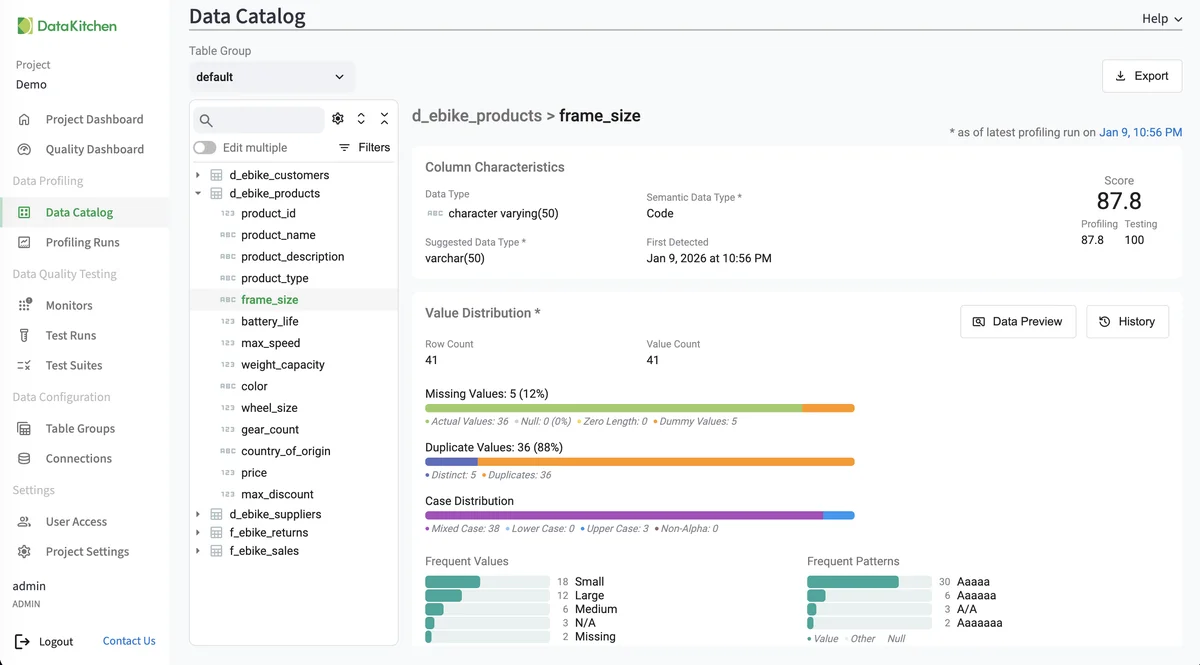
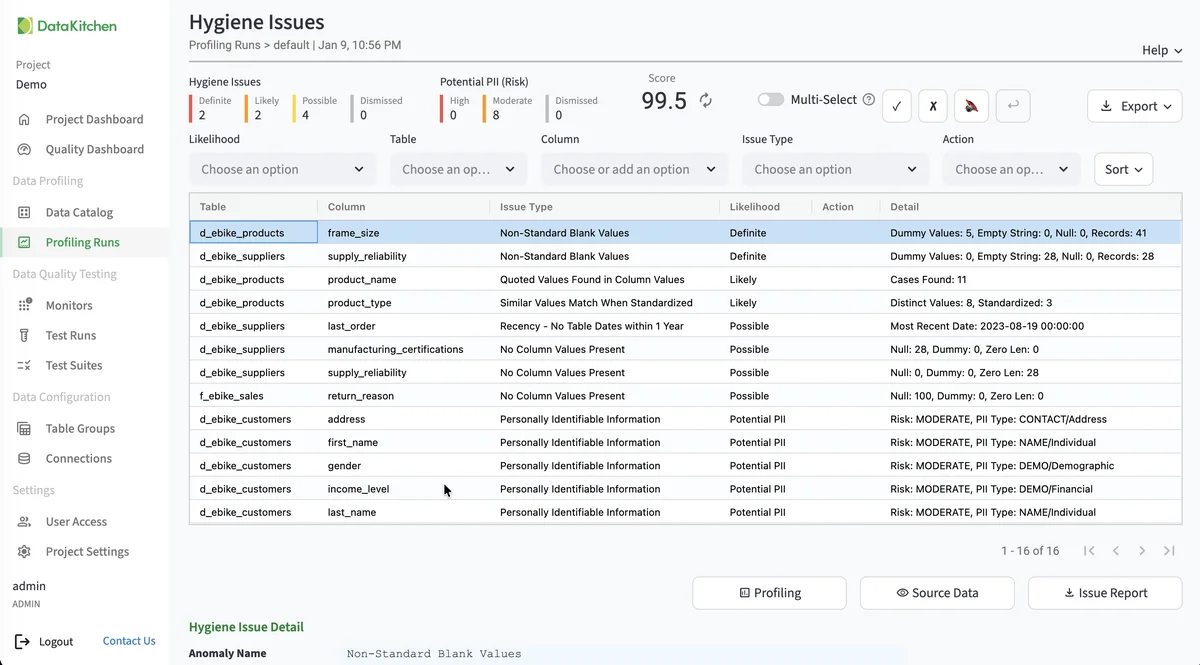
DataKitchen Data Observability Installer is a command-line tool that sets up two open-source data products on your own infrastructure: TestGen, which profiles data, generates data quality tests, and monitors for anomalies; and Observability, which tracks data journeys across multi-tool pipelines and alerts on issues. The installer supports two modes — Docker Compose (recommended) for persistent team use, and a pip-based mode using uv and an embedded PostgreSQL for evaluation without Docker. Minimum requirements are 2 CPUs, 8 GB RAM, and 20 GB disk. TestGen exposes a Streamlit UI on port 8501 and an API/MCP endpoint on 8530; Observability serves its UI on port 8082. Both products are Apache 2.0 licensed and maintained by DataKitchen.
Should you self-host data-observability-installer?
data-observability-installer scores 43/100 on selfhost.directory (how scoring works) and ranks #2 of 3 in Data Engineering. It has 143 GitHub stars.
It shipped 1 stable release in the past year. The latest, latest, came out on 15 May 2026.
Setup is moderate: expect some configuration beyond a single command. It is Apache-2.0-licensed and written mostly in Python.
Its closest alternative on selfhost.directory is airbyte (75/100, 22 282 stars). It scores higher overall, so compare the two before you pick. See data-observability-installer vs airbyte side by side.
Features
- Agent heartbeat monitoring
- Anomaly Detection
- CI/CD Integration
- Data observability / Data Journeys
- Data Profiling
- Data quality test generation
- Demo data generation
- Dual install modes (Docker Compose / pip)
- MCP (Model Context Protocol) server
- Notification rules and alerts
data-observability-installer README
More in Data Engineering
 lakehouse-at-homeSelf-hosted lakehouse for local data engineering with Spark, Iceberg, and Kafka via Docker Compose, plus optional Airflow and test data tools.
 MyDuck ServerMyDuck Server is a self-hosted, open-source analytics server with MySQL/PostgreSQL wire protocols and DuckDB's OLAP engine for 1000x faster queries.
 PontoonPontoon is a self-hosted, open-source data export platform for vendors to send data directly to customer warehouses like Snowflake, BigQuery, Redshift, and Postgres.
 prefectPrefect is a self-hosted, open-source workflow orchestration framework turning Python functions into production data pipelines with scheduling, retries, and caching.
 sparklabxSelf-hosted Apache Spark notebook platform with per-user PySpark/Scala kernels, MinIO IAM storage isolation, OAuth, and Helm deployment. Open-source core, Apache-2.0.
 airbyteAirbyte is a self-hosted data movement platform with hundreds of connectors for ELT pipelines and AI agents, deployable via Docker, Kubernetes, and abctl CLI.
 Apache AirflowApache Airflow - A platform to programmatically author, schedule, and monitor workflows
0 comments