Self-host crawlseo
v0.3.5Open-source SEO dashboard: GSC, site crawler, Web Vitals
docker compose up -d- Stars
- 655
- Port
- 3000 (Web app HTTP port (compose maps 3000:3000))
- Requires
- PostgreSQL
ghcr.io/crawlseo/crawlseo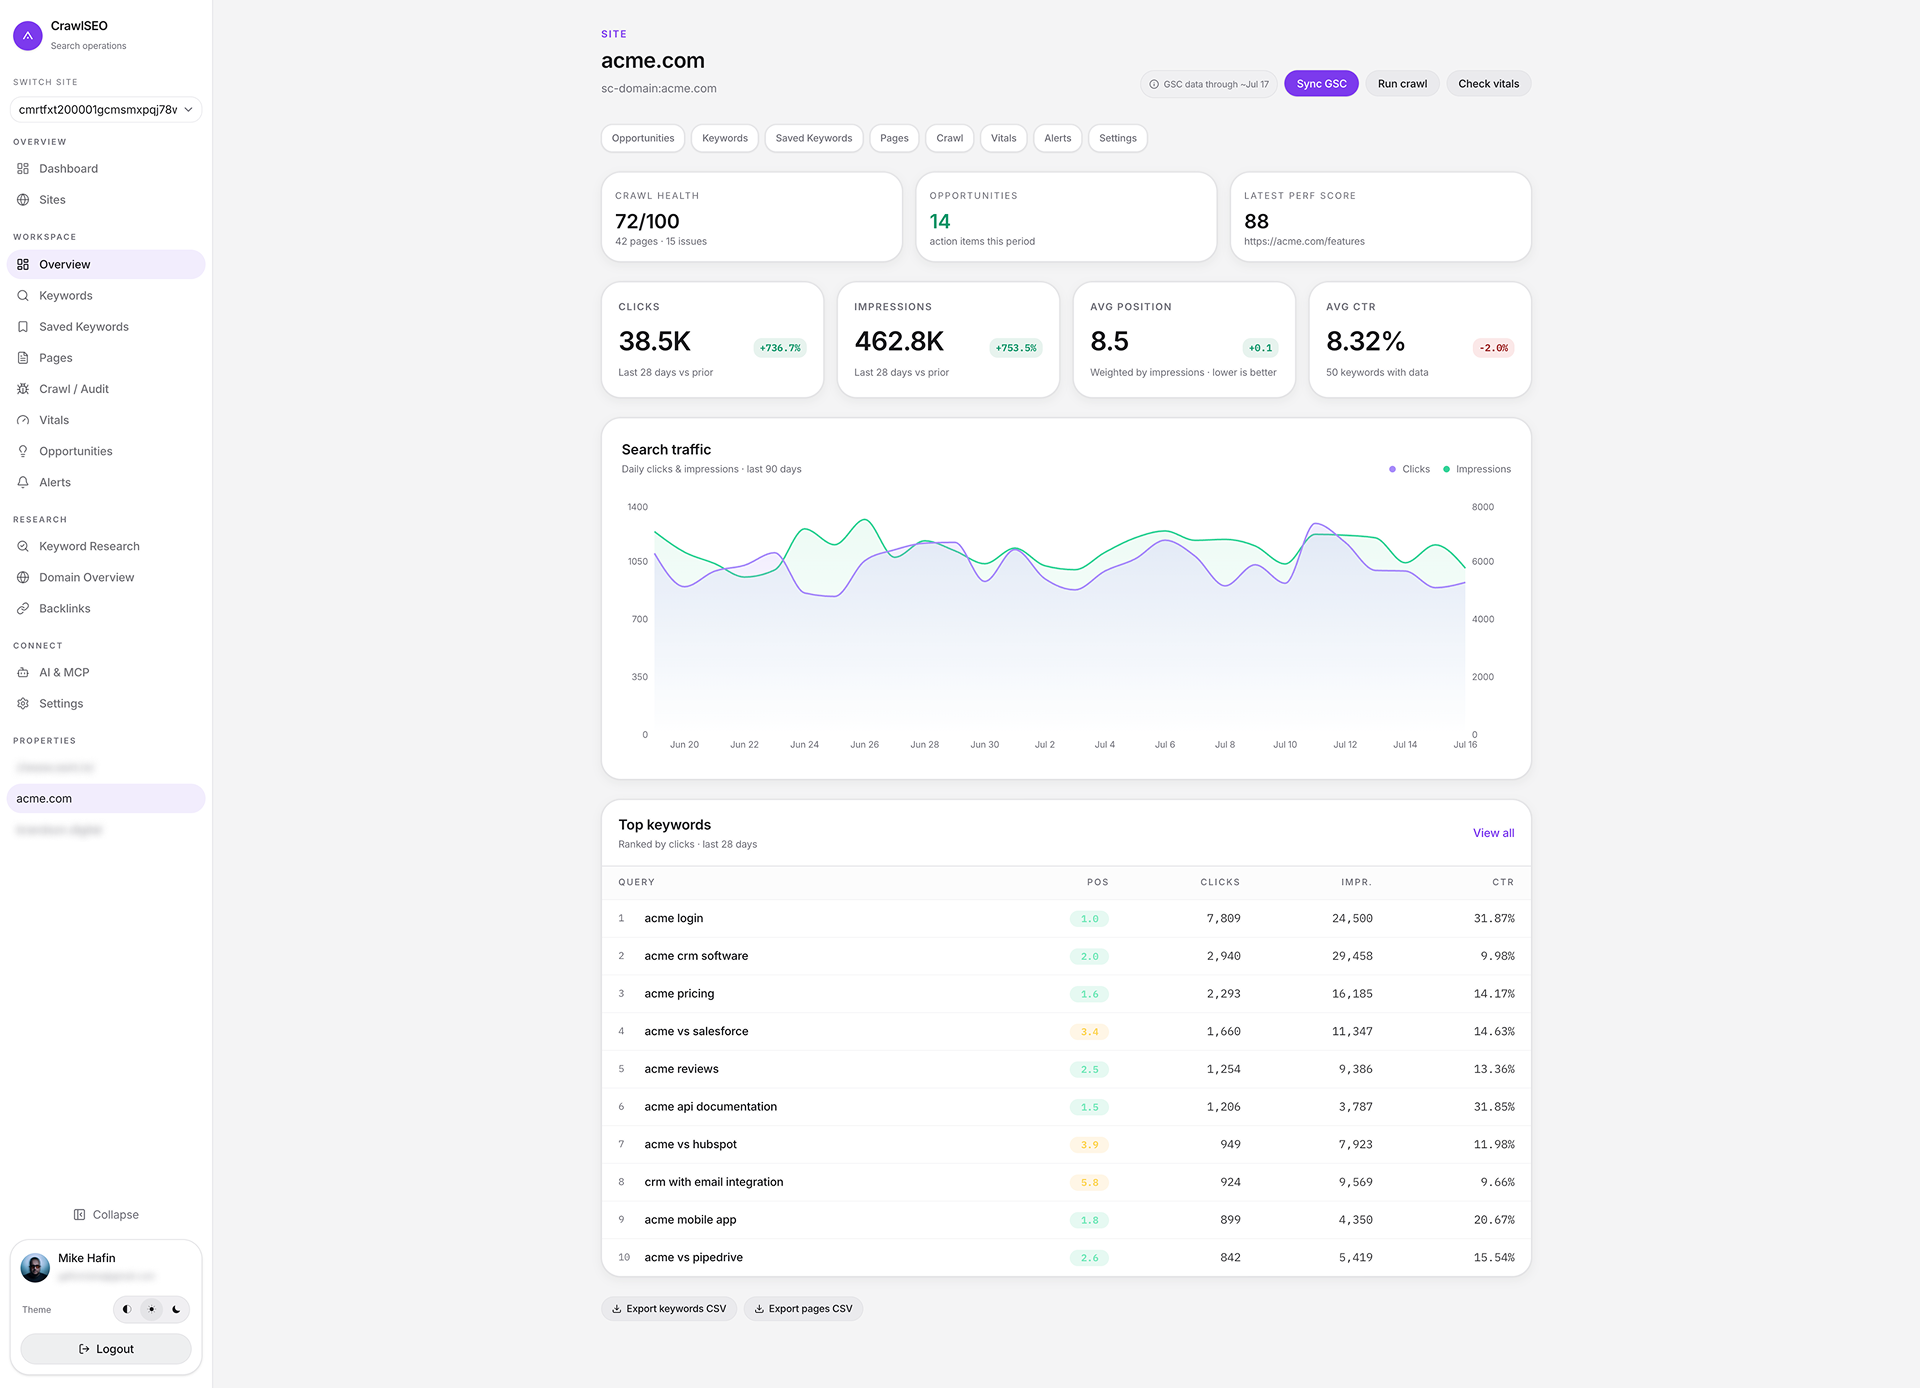
What is crawlseo?
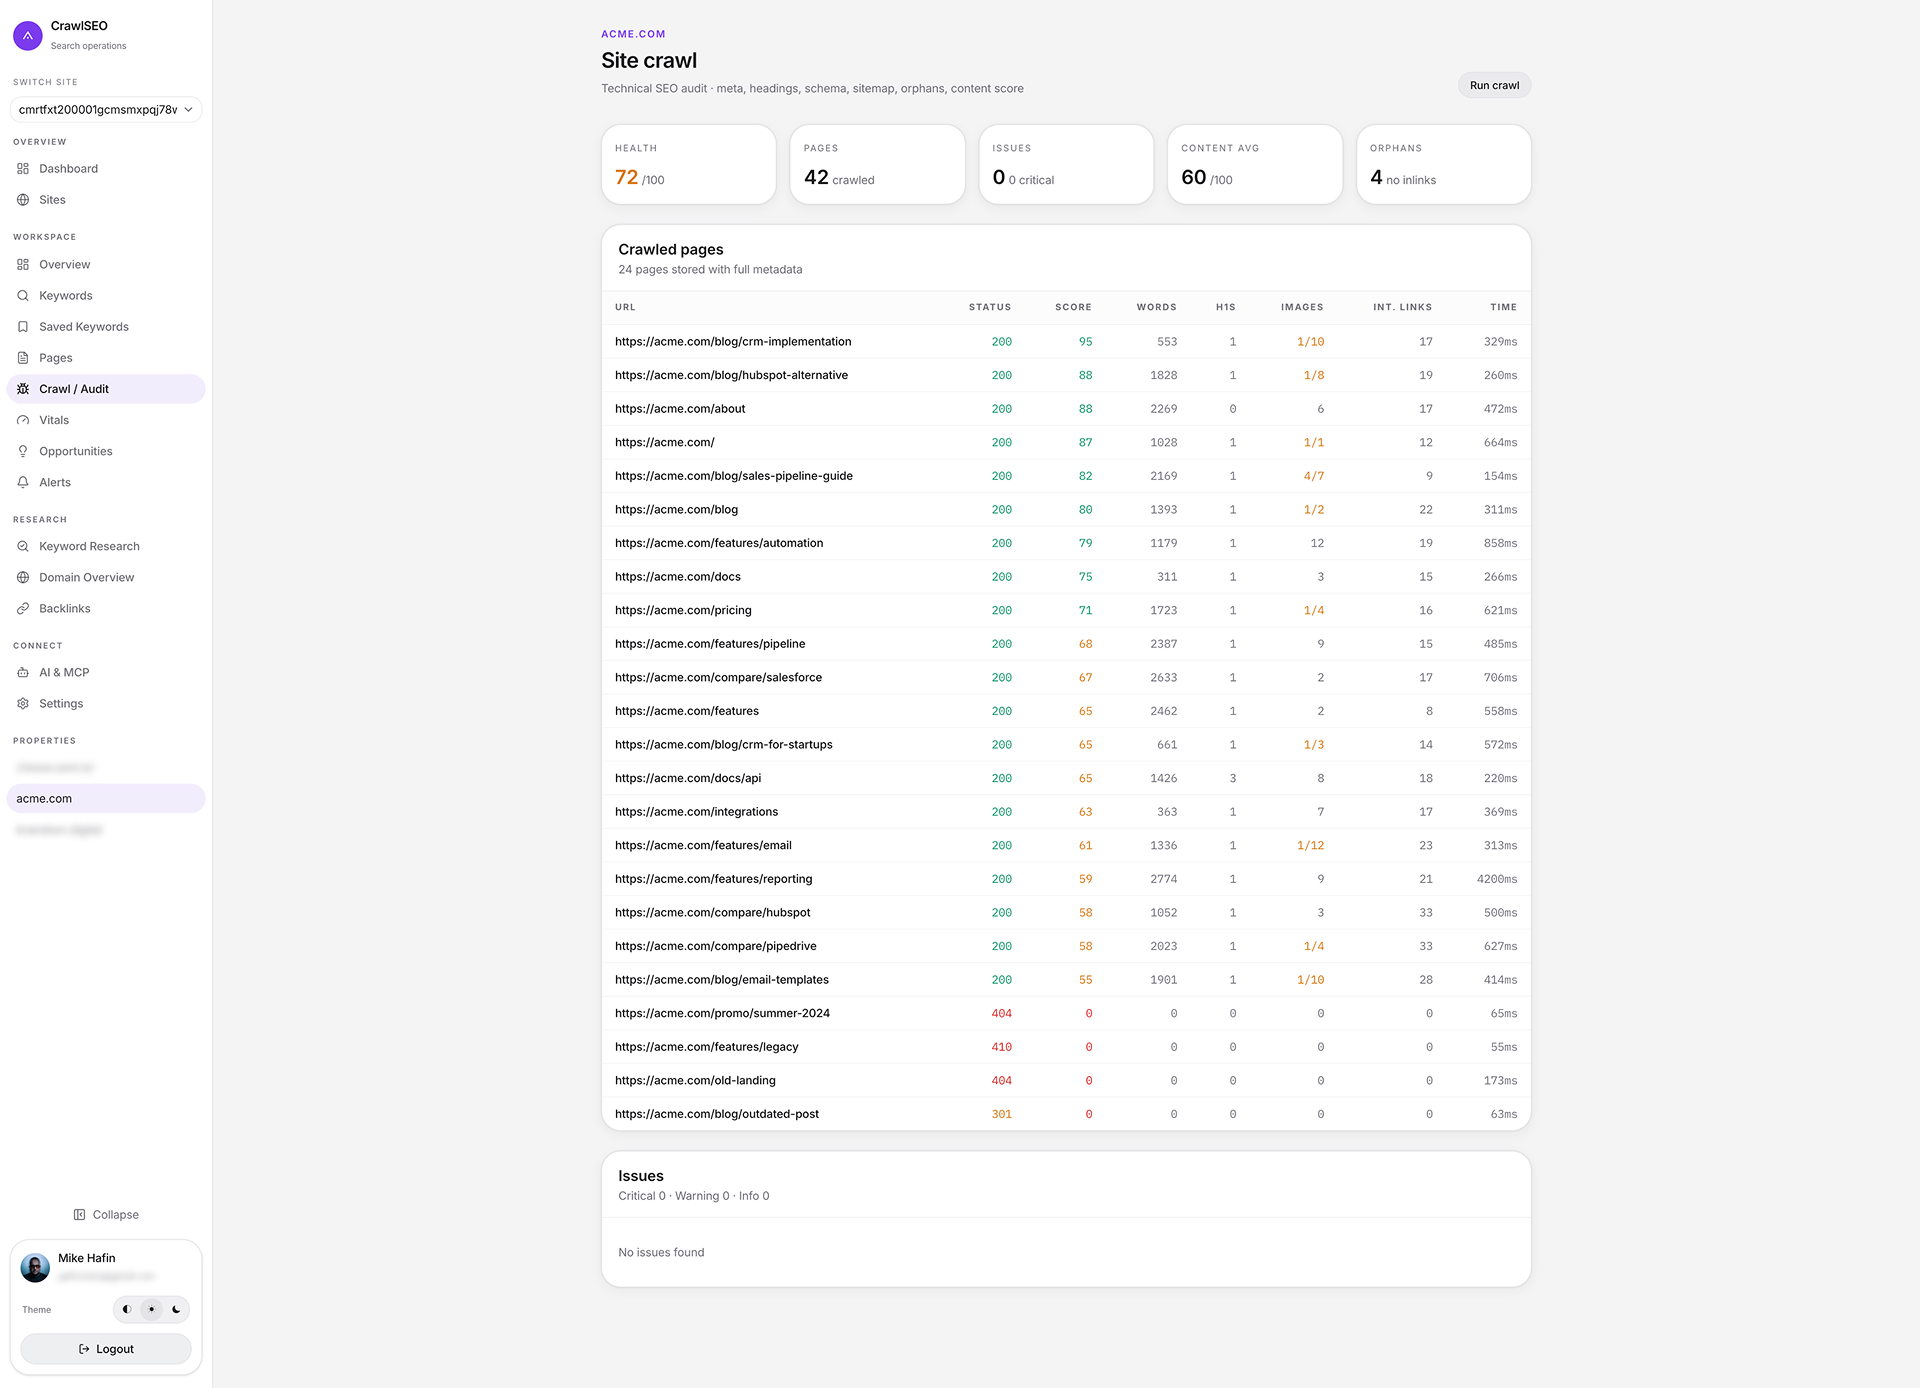
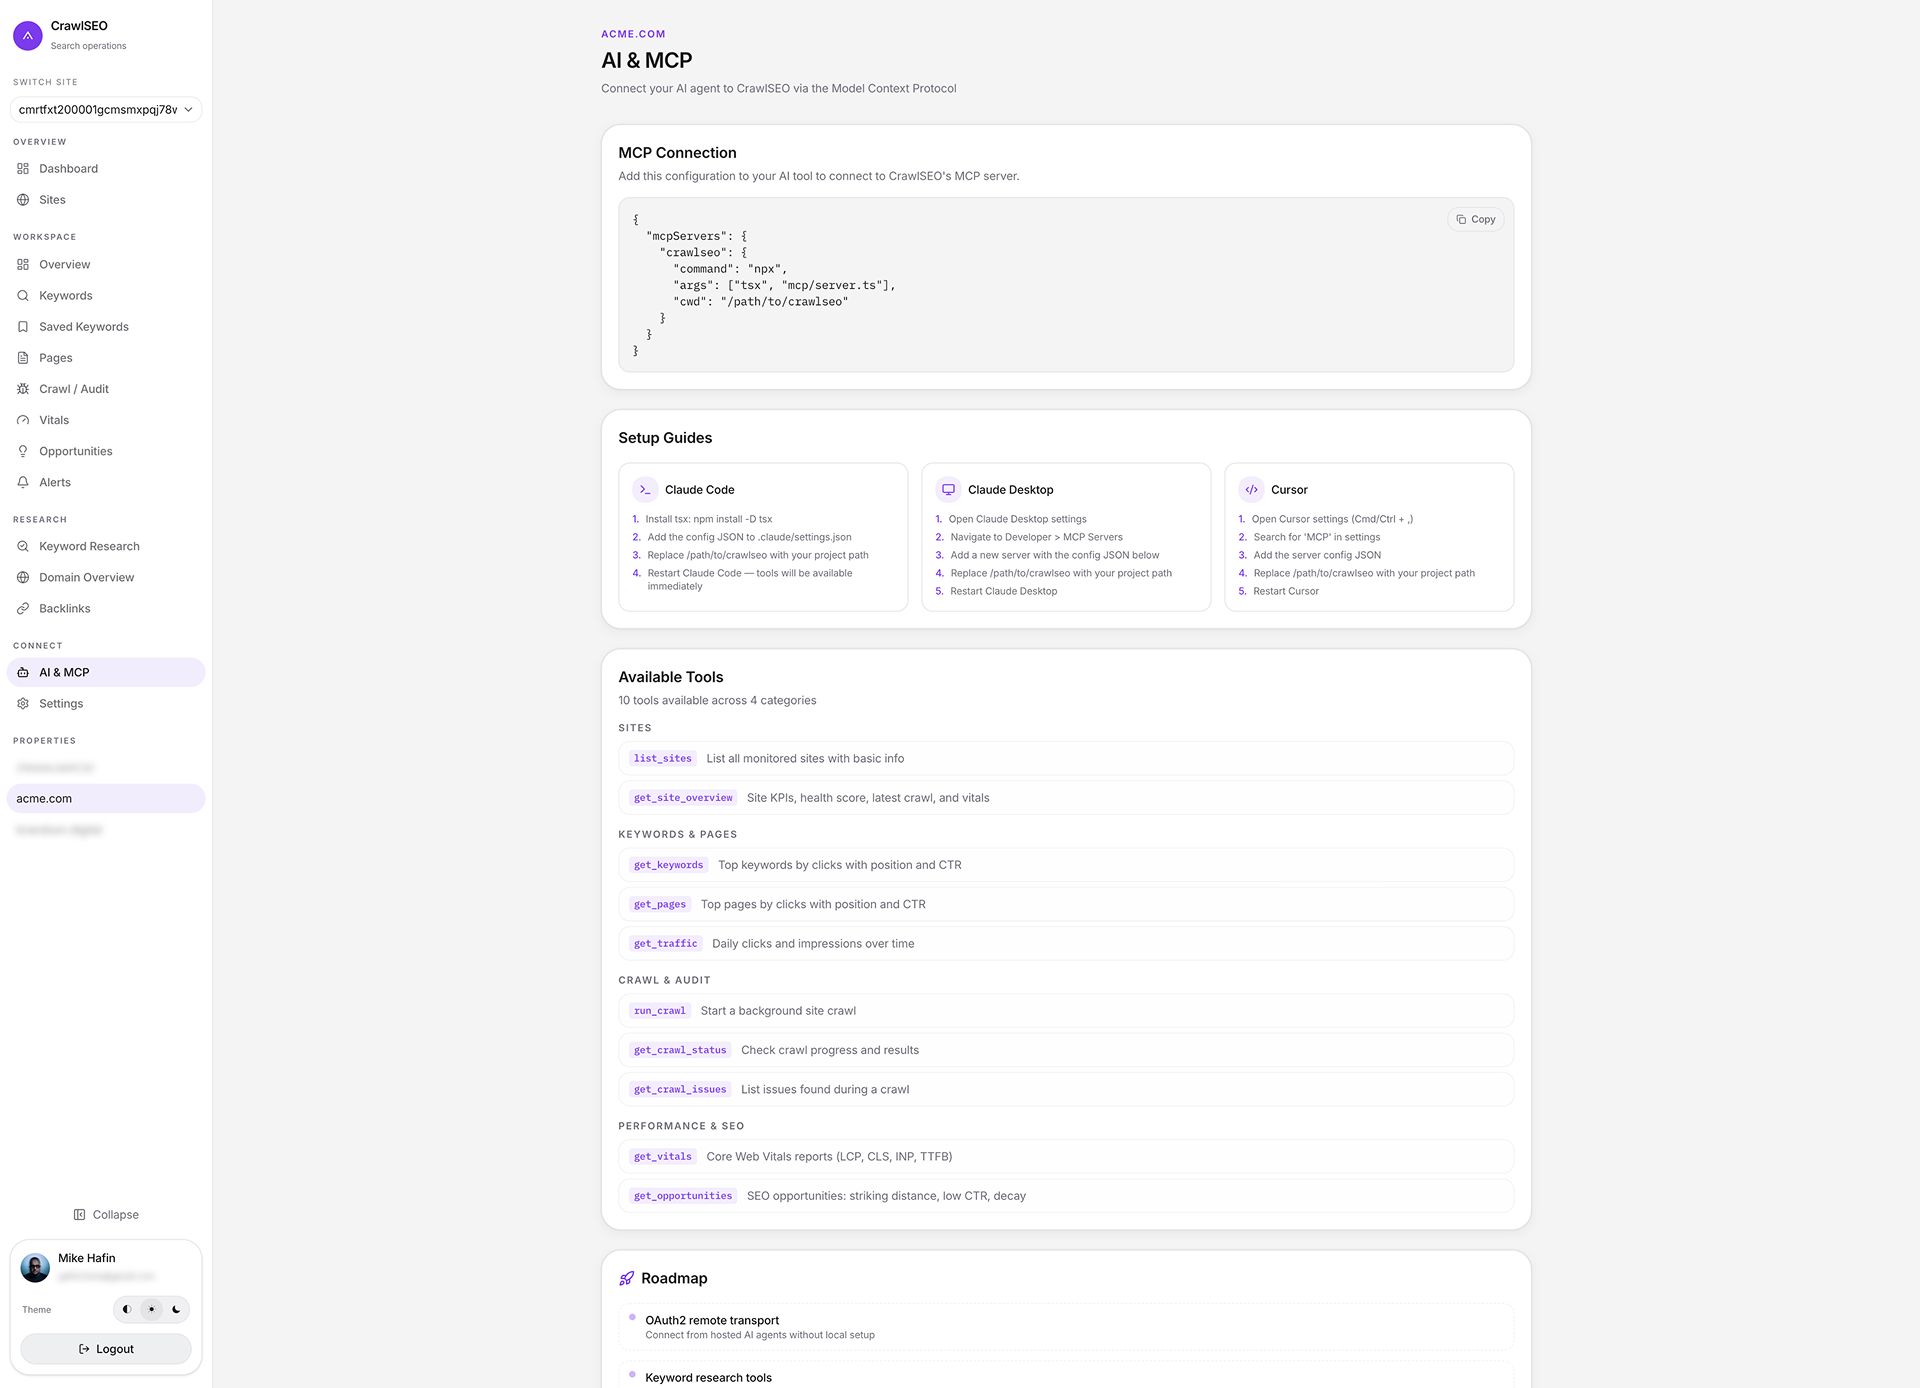
crawlseo is an MIT-licensed SEO monitoring app aimed at founders and small teams rather than SEO specialists. It imports Google Search Console metrics (queries, pages, clicks, impressions, position, with 28-day comparisons), audits sites with a crawler that fetches a maximum of 2000 pages per run and obeys robots.txt, measures LCP, CLS, INP and TTFB through PageSpeed Insights, and covers keyword ideas, referring-link data, historical rankings, optimization opportunities, alerting and CSV downloads. Keyword and backlink numbers use a bring-your-own-key DataForSEO account, falling back to free Google autocomplete suggestions; an optional Bing Webmaster Tools sync is available. Language models like Claude Code can query an instance over the MCP protocol at /mcp or stdio using hashed access keys, backed by nine read-only tools and a /api/v1 JSON API with rate limiting. Self-hosting runs through Docker Compose with three services — web app, background worker and PostgreSQL — pulling a prebuilt image from GitHub's container registry (amd64 and arm64), with migrations applied on container start; Node.js 20+ plus a database can also be used manually, or Vercel for light setups. You must create your own Google OAuth client to sign in, and the server defaults to publishing port 3000 in plain HTTP, so the guide recommends loopback binding behind a TLS reverse proxy and closing registration. The project is pre-1.0 (v0.3.4 as of October 2026), and AI-answer tracking (Perplexity) exists only in the paid crawlseo.cloud hosted product, not in the self-hosted code.
Should you self-host crawlseo?
crawlseo scores 46/100 on selfhost.directory (how scoring works) and ranks #31 of 41 in Search Engines. It has 655 GitHub stars.
It shipped 10 stable releases in the past year. The latest, v0.3.5, came out on 26 October 2026.
Setup is moderate: expect some configuration beyond a single command. An official Docker image is available. It is MIT-licensed and written mostly in Typescript.
Its closest alternative on selfhost.directory is openseo (72/100, 25 472 stars). It scores higher overall, so compare the two before you pick. See crawlseo vs openseo side by side.
Features
- AlertsNothing is sent by email or chat yet; evaluation runs on demand, after syncs, or on the schedule.
- Alert webhooks
- Background job queue
- Backlink Analysis
- Core Web Vitals
- CSV Export
- Keyword Research
- MCP Server
- Rank Tracking
- Read-only REST API
- Scheduled syncs and crawlsScheduled crawls and vitals checks run on Docker (worker or inline app), not on Vercel.
- Search Console analytics
- SEO opportunity detection
- Site crawler
crawlseo README
FAQ
Is there a free plan?
Self-hosting is free; the cloud plans are paid and open in waves via a waitlist.
What is the difference between the open-source version and the cloud?
The open-source version is SEO monitoring you run on your own server under MIT; the cloud adds hosting, scheduled runs and AI-engine visibility measurement.
Why is Search Console required?
It confirms the site belongs to you, and its queries are the starting point for the prompts.
Who is it for?
Founders and small teams who want to see how their site performs in search and AI answers without becoming SEO specialists.
What does crawlseo do?
It reads your Search Console data, checks your site, and asks Perplexity the questions your customers ask, showing where your site is named and which sources are cited.
More in Search Engines
 degoogSearch engine aggregator with a comprehensive plugin/extension system
 directory-indexerA self-hosted MCP server that indexes local folders into a searchable knowledge base for AI assistants using local embeddings and a vector store.
 elasticsearchOpen-source distributed search engine that handles structured, unstructured, and vector data for real-time search, observability, and AI workloads.
 FessFess is a self-hosted, open-source enterprise search server built on OpenSearch that crawls websites, files, and databases for full-text search with AI/RAG.
 Flamehaven-FilesearchSelf-hosted RAG search engine with BM25+semantic hybrid search across 34 formats, multi-LLM support (Gemini, OpenAI, Claude, Ollama) for private document search.
 FredyFredy monitors 29 European property portals, deduplicates listings, calculates affordability and travel times, sends notifications via Slack, Telegram, Email, Discord.
 GeoLookSelf-hosted, open-source GEO platform for AI search visibility. Runs locally with Python 3.9+, covers 17 engines, closes the loop from analysis through auto-verification.
 HisterA self-hosted private search engine that indexes visited web pages and local files for full-content search from web, terminal, or MCP AI assistants.
 houndOpen-source source code search engine: a Go backend indexes every configured repository and a React UI runs regex queries against a trigram index.
 How-to-host-LibreXFramework and javascript free privacy respecting meta search engine
 hubgrep_searchHubGrep is a self-hosted, open-source search engine that queries multiple code-hosting platforms simultaneously, treating all services equally.
 librecrawl-technical-seo-audit-mcpSitewalk is a self-hosted, open-source SEO crawler running inside AI assistants via MCP, with unlimited audits, 50+ checks, PDF reports, and zero data retention.
0 comments